Find exceptional developers at Hourlydeveloper. Get the expertise, solutions, and teamwork you need for success. Hire developers easily and boost your projects today!
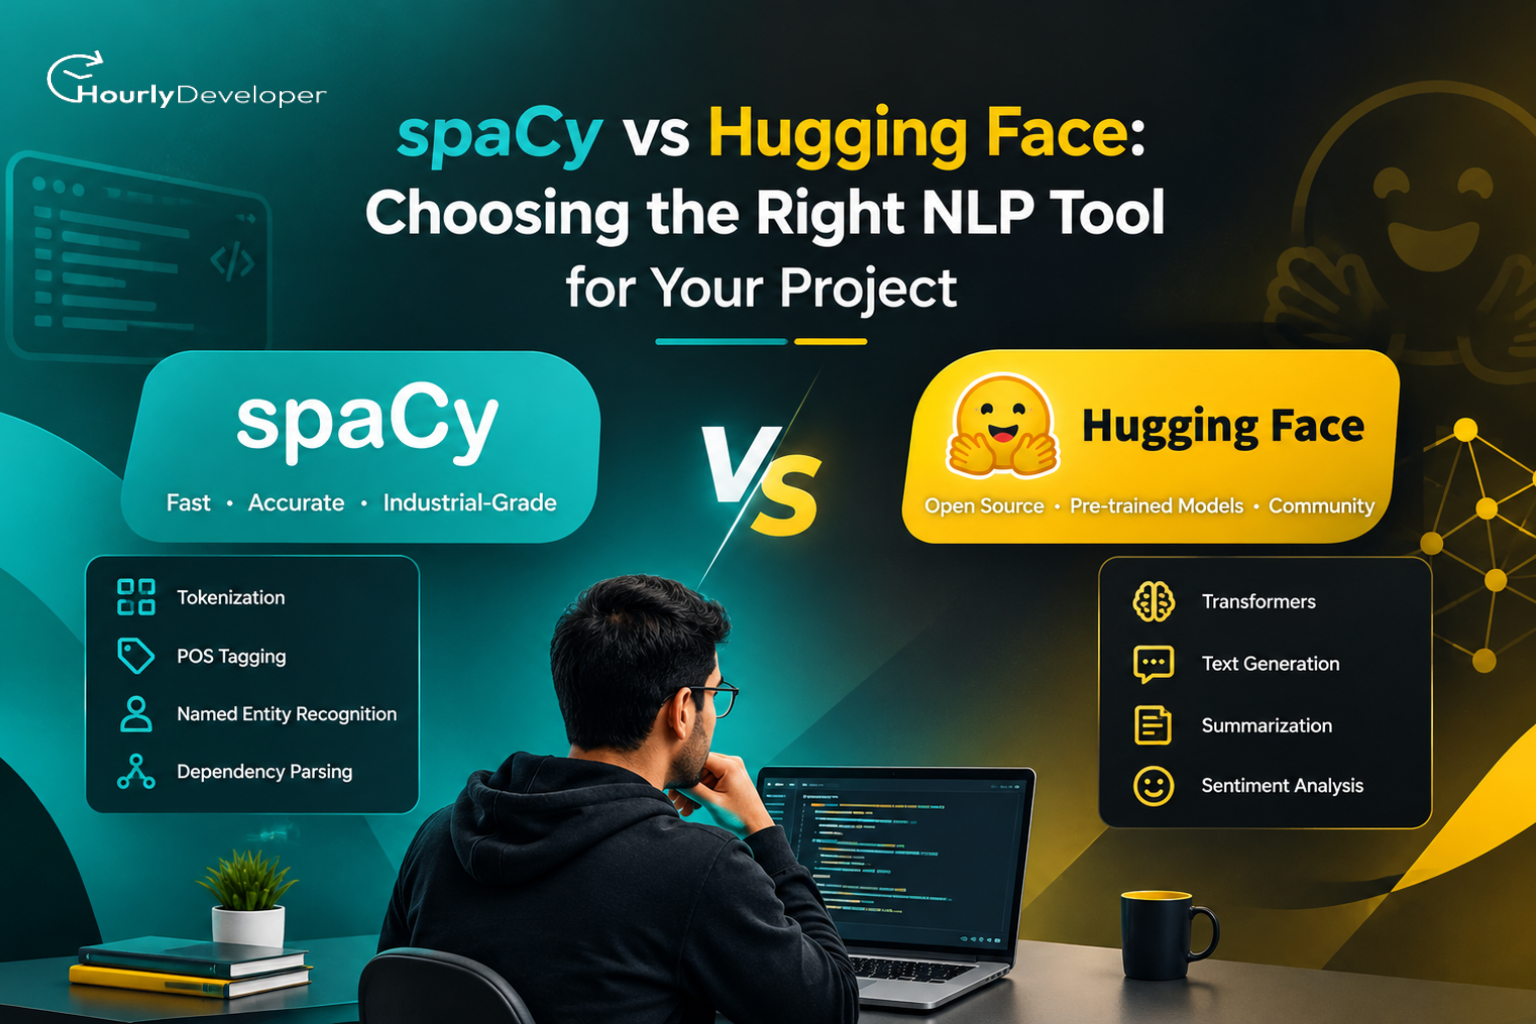
spaCy vs Hugging Face: Choosing the Right NLP Tool for Your Project
Natural language processing has quietly become part of almost every product built today, from customer support chatbots to resume screening tools to search bars that understand what you actually meant to type. Once a team decides to work with text data, one question comes up almost immediately: which is better spaCy or Hugging Face? Both are Python libraries, both are free and open source, and both show up constantly in job postings, tutorials, and GitHub repositories. That overlap is exactly what makes the decision confusing.
This is not a case of one tool being outdated and the other being new. Both are actively maintained, both are used in production by large companies, and both solve real problems well. The right choice depends on what you are building, how much control you need over the underlying models, and how your team already works. This guide walks through the practical differences between the two, in plain language, so you can make a decision that fits your project rather than whichever tool happens to be trending that week.
What Is spaCy?
spaCy is an open-source Python library built specifically for production natural language processing. It was created by Explosion, a company founded by Matthew Honnibal and Ines Montani, and it was designed from day one to be fast and easy to put into a real application, not just a research notebook. When people use spaCy, they are usually doing things like breaking a sentence into words, called tokenization, identifying names of people, places, and companies in text, known as named entity recognition, understanding grammatical structure through part of speech tagging and dependency parsing, or grouping similar documents together.
What makes spaCy popular with engineering teams is its consistency. You load a model, run it on your text, and get a predictable object back with all the linguistic information already attached. There is very little guesswork involved. spaCy also ships with pretrained pipelines for more than 70 languages, so a team working on a multilingual product does not have to start from scratch for each new language.
Since version 3, spaCy has also added support for transformer based models, which means it can now use the same kind of deep learning models that Hugging Face is known for, while still keeping its clean, structured API on top. This makes spaCy a strong choice when a team wants NLP that behaves like a normal software library rather than a research experiment. For many teams, choosing an NLP framework for business applications starts right here, with a tool built to run inside production software rather than a lab notebook.
What Is Hugging Face?
Hugging Face is best known for its Transformers library and its Model Hub, which hosts hundreds of thousands of pretrained models contributed by researchers, companies, and individual developers. Where spaCy gives you a structured pipeline, Hugging Face gives you direct access to the model itself, along with the tools needed to fine tune it, evaluate it, and deploy it.
Hugging Face is less a single tool and more of an ecosystem. Alongside Transformers, it includes Datasets for loading and processing training data, Tokenizers for fast text preprocessing, Accelerate for training across multiple GPUs, and Spaces for hosting demos. This ecosystem is why Hugging Face is the default starting point for teams working with large language models, whether that is a BERT based classifier or a modern generative model.
The tradeoff is that Hugging Face gives you more raw power and more decisions to make. You sit closer to the model weights and the training loop, which is exactly what a research team or an ML engineer building something custom usually wants. For a team that just needs reliable entity extraction without touching model internals, this flexibility can feel like extra work rather than an advantage. Even so, Hugging Face is routinely named among the best NLP framework for AI development options for teams that need the newest generative or research grade models.
So, Which Is Better, spaCy or Hugging Face?
If you want one sentence to remember, it is this: spaCy is built for using NLP inside an application, while Hugging Face is built for working with the models themselves. spaCy hands you a finished pipeline. Hugging Face hands you the raw materials and the workshop to build one. Neither answer to Which is better spaCy or Hugging Face is universally correct. A support ticket classifier processing 2 million messages a day on a modest server has different needs than a research team fine tuning a custom language model. The rest of this guide breaks the decision down by the factors that actually matter in practice.
How Each Library Actually Works, in Plain Terms
It helps to picture what happens the moment you hand a sentence to each tool. With spaCy, you call one function, and the library runs the sentence through a series of small, specialized steps in sequence, one that splits words apart, one that tags each word's grammatical role, one that finds names and places, and so on. Each step is fast because it was trained to do exactly one job well. By the time the sentence comes back to you, it already has every layer of information attached and organized, ready to read off directly in code.
Hugging Face works differently underneath. A transformer model reads the whole sentence at once and builds a mathematical representation of it based on patterns learned from enormous amounts of text during training. That representation is powerful and flexible, which is why the same underlying model architecture can be adapted to translation, summarization, or question answering just by changing how the output is used. The cost of that flexibility is that the model does more heavy computation per sentence, which is exactly why it tends to need stronger hardware to run quickly.
Neither approach is more correct than the other. spaCy's step by step design is closer to a well organized assembly line. Hugging Face's transformer approach is closer to a single expert reading the whole page and forming a judgment. Knowing this difference makes it much easier to predict how each tool will behave once your project is live and under real traffic, rather than just in a demo.
Common Mistakes Teams Make When Choosing Between Them
A few patterns show up again and again in projects that end up needing a rebuild a few months after launch.
• Picking Hugging Face for a simple tagging task because it feels more modern, then discovering GPU hosting costs eat the budget within weeks
• Picking spaCy for a generative or summarization feature it was never designed to handle, then patching around the gap with fragile workarounds
• Benchmarking only on demo sentences instead of real, messy customer data, which hides how each tool handles typos, slang, or mixed languages
• Skipping a proof of concept entirely and committing to one tool based on a blog post or a colleague's opinion from a different project
• Underestimating the ongoing work of retraining and monitoring a model once real users start sending it text nobody anticipated during testing
Data Privacy and Security Considerations
For businesses handling customer data, contracts, medical notes, or financial records, where the model actually runs matters as much as how accurate it is. spaCy models run entirely on your own infrastructure by default, which makes it simpler to keep sensitive text inside your own network boundary and satisfy data residency requirements common in healthcare and finance.
Hugging Face also supports fully local, self hosted deployment, so this is not a difference in what is possible, only in what teams tend to do by default. Because Hugging Face is closely associated with hosted inference and its public hub, some teams reach for hosted endpoints out of convenience, which then requires reviewing where text is sent and processed before handling anything regulated. Either tool can be made compliant, but this is a conversation worth having with your security team before, not after, a pilot project touches real customer records.
Scaling Considerations as Your Product Grows
A tool that works fine at 10,000 requests a day can behave very differently at 10 million. spaCy pipelines scale in a fairly predictable way, adding more CPU instances behind a load balancer tends to keep pace with growing traffic, since each request is cheap and fast. Costs rise roughly in a straight line with volume, which makes budgeting easier for finance teams.
Hugging Face based systems scale differently. Batching multiple requests together before sending them to a GPU can dramatically improve throughput, but it also adds engineering complexity around queuing and latency targets. Many teams that scale a Hugging Face model successfully end up building a small internal serving layer just to batch requests efficiently. This is manageable with the right expertise, but it is worth planning for early rather than discovering it under load during a busy launch week. This is often the point where teams decide tohire AI ML developerswith hands on scaling experience, rather than learning these lessons in production.
spaCy vs Hugging Face: Side by Side Comparison
Factor
spaCy
Hugging Face
Primary focus
Ready made NLP pipelines for applications
Access to and training of the underlying models
Typical speed on CPU
Fast, optimized in Cython
Slower, often needs a GPU for larger models
Best known for
NER, POS tagging, dependency parsing
Text generation, classification, translation, summarization
Learning curve
Gentle, consistent API
Steeper, requires ML background for fine tuning
Model selection
Curated, task focused pipelines
Vast public Model Hub, nearly any NLP task
Multilingual support
70+ languages built in
Depends on the model chosen from the Hub
Customization
Custom training plus pluggable transformers
Full control over architecture and fine tuning
Deployment footprint
Lightweight, easy to package
Larger, often needs GPU provisioning
Community type
Application developers, NLP practitioners
Researchers, ML engineers, LLM builders
Licensing cost
Free, open source
Free, open source
Speed and Performance
For traditional NLP tasks like tokenization, part of speech tagging, and named entity recognition, spaCy is noticeably faster, especially on CPU. Its core is written in Cython, which compiles down close to C speed, and its pipelines are optimized to process large volumes of text quickly. A team processing millions of documents a day, such as scanning support tickets or news articles, will usually see lower latency and lower server costs with spaCy.
Hugging Face models, especially the larger transformer based ones, are more resource intensive. They generally need a GPU to run at a reasonable speed, particularly during training. On CPU, a large transformer model can run 10 to 20 times slower than an equivalent spaCy pipeline for a simple task like entity recognition. This does not make Hugging Face models a poor choice, it just means the hardware and infrastructure planning looks different. If your project depends on quick responses at high volume without a GPU budget, this is worth weighing early, not after launch.
Model Availability and Task Coverage
This is where Hugging Face has a clear edge. The Model Hub currently hosts models for almost every NLP task imaginable, translation, summarization, question answering, sentiment analysis, and text generation, along with a growing number of image and audio models too. If a research lab published a new model last month, there is a good chance it is already on the Hub with example code ready to copy.
spaCy's strength is depth rather than breadth. It covers the core linguistic tasks extremely well, but it is not trying to be a home for every model that exists. It focuses on doing NER, tagging, and parsing reliably, and it lets you plug in a Hugging Face transformer underneath if a specific component needs more power. Many teams end up using both for exactly this reason.
Ease of Use and Learning Curve
spaCy was built with developer experience as a priority. Its documentation is clear, its API stays consistent across tasks, and a developer with basic Python knowledge can have a working NLP pipeline running within an hour. This matters a lot for smaller teams or teams without a dedicated machine learning specialist on staff.
Hugging Face has a steeper learning curve, not because the library is poorly designed, but because the concepts involved, such as tokenizer alignment, attention masks, and model checkpoints, require some background in how transformer models actually work. Teams with a machine learning engineer will find this manageable. Teams without that background often need a few weeks of ramp up time before they feel productive.
Customization and Flexibility
If your project needs a highly customized model, trained on your own data with full control over architecture and training, Hugging Face is the stronger foundation. You can fine tune an existing model on your own labeled data, adjust training settings, and export the result in formats ready for production serving.
spaCy also supports custom training and even lets you plug in Hugging Face transformers as a component inside its pipeline through its spacy-transformers extension. This gives teams a middle path: keep spaCy's clean pipeline structure while still benefiting from a strong pretrained transformer underneath. For most business applications that need custom entity types or domain specific classification, this hybrid approach covers the need without requiring a full move to raw model code.
Deployment and Production Readiness
spaCy pipelines are lightweight and package neatly, which makes deployment straightforward. A trained spaCy model can be packaged as a small Python module and dropped into an existing service with minimal setup. This is one reason spaCy shows up so often in production systems at companies that need dependable, low-maintenance NLP.
Hugging Face models can also be deployed in production, and the ecosystem has matured a lot for this purpose, with tools for hosted inference, model export, and quantization to shrink model size. But deployment usually requires more planning, including GPU provisioning, memory management for larger models, and monitoring for latency under load. None of this is a dealbreaker, but it is more infrastructure work than spinning up a spaCy pipeline.
Community and Support
Both libraries have large, active communities, but they attract slightly different crowds. spaCy's community leans toward software engineers and NLP practitioners building applications. Hugging Face's community leans toward researchers, ML engineers, and anyone experimenting with newer models, including large language models. Hugging Face also runs a very active public hub of shared models and datasets, which means a lot of community effort goes into pretrained resources rather than forum discussions alone.
Cost Considerations
Both spaCy and Hugging Face are free and open source, so there is no license fee for either one. The real cost difference shows up in infrastructure. spaCy pipelines usually run comfortably on standard CPU servers, keeping hosting costs low and predictable. Hugging Face projects that rely on larger transformer models often need GPU instances, which cost significantly more per hour, plus the engineering time to manage that infrastructure. A useful rule of thumb: budget for compute, not for licensing, when comparing the two. Cost is often the deciding factor when choosing an NLP framework for business applications on a fixed budget rather than an unlimited research grant.
Where the NLP Market Is Heading
Analyst estimates vary, but the direction is consistent across every report. Several major research firms put the global NLP market somewhere between $36 billion and $52 billion in 2025, with growth projections in the 20 to 30 percent CAGR range through the early 2030s. That growth is exactly why picking the right foundation matters more now than it did 5 years ago. Choosing the wrong tool early often means rebuilding a pipeline later, at real cost in engineering time. It also explains why spaCy and Hugging Face are consistently named among the best NLP framework for AI development teams evaluate before committing to a build.
When spaCy Is the Better Choice
• You need fast, predictable entity recognition, tagging, or parsing running in production
• Your team does not have a dedicated machine learning engineer on staff
• You are processing large volumes of text on CPU servers without a GPU budget
• You need multilingual support out of the box for common languages
• You want a stable pipeline that does not require deep transformer knowledge to maintain
When Hugging Face Is the Better Choice
• You need access to the newest, most capable models, including large language models
• Your project goes beyond core NLP, into summarization, translation, or text generation
• You have in-house ML expertise to fine tune and manage models responsibly
• You are building something research heavy or need full control over model architecture
• You want to start from a huge library of pretrained community models rather than build from zero
Can You Use Both Together?
Yes, and this is more common than most teams realize. The spacy-transformers extension lets a Hugging Face model sit inside a spaCy pipeline as one component. You get spaCy's structured API for loading, training, and serving, while the Hugging Face model underneath supplies stronger accuracy for a specific task like entity recognition on messy, informal text. A typical pattern looks like this: use plain spaCy for fast, general processing across your whole document set, then route only the harder cases, such as ambiguous entities or low confidence predictions, to a heavier transformer model. This keeps average latency low while still getting stronger results where it counts.
Real Business Use Cases
The right tool often becomes obvious once you look at what a specific industry actually needs to do with text, rather than debating the two libraries in the abstract. Below are patterns pulled from how teams in different sectors typically split the work between the two. Businesses without this experience already on staff often hire AI ML developers who have built these exact patterns before, rather than testing approaches from scratch inside a live product.
• E-commerce: spaCy for fast product tagging and catalog cleanup at scale, Hugging Face for review sentiment models trained on your own product categories
• Healthcare: Hugging Face for extracting structured data from clinical notes where accuracy on specialized medical language matters more than raw speed
• Finance: spaCy for high volume document scanning and entity extraction across contracts and filings, with Hugging Face models layered in for fraud pattern detection in text
• Customer support: spaCy for routing tickets by intent and urgency at low latency, Hugging Face for a more capable chatbot that needs to generate natural responses
• Legal: Hugging Face for deep clause level contract analysis, spaCy for quickly flagging named parties, dates, and monetary values across large document sets
• Recruitment and HR: spaCy for parsing resumes and extracting skills, names, and experience quickly across thousands of applications
Choosing an NLP Framework for Business Applications
This decision usually comes down to five practical questions. Answer them honestly before writing any code, and the right path tends to become obvious.
1. What is the core task? Entity extraction and tagging point toward spaCy. Generation, summarization, or deep classification point toward Hugging Face.
2. What hardware do we have? CPU only environments favor spaCy. If GPUs are already part of your stack, Hugging Face is easier to justify.
3. Who is maintaining this long term? A small engineering team without ML specialists will find spaCy easier to keep running reliably.
4. How much text are we processing, and how fast does it need to happen? High volume, low latency workloads usually favor spaCy or a hybrid setup.
5. Do we need the newest models, or proven, stable ones? Cutting into new model releases quickly favors Hugging Face. Stability favors spaCy.
Why the Right Team Matters as Much as the Right Tool
Even the best framework will underperform in the hands of a team unfamiliar with its tradeoffs. Getting spaCy or Hugging Face into production well means understanding not just how to load a model, but how to evaluate it against real data, monitor it once it is live, and retrain it as language and user behavior shift over time. This is where a lot of projects quietly stall after the initial prototype looks promising.
This is why many companies choose to hire AI ML developers on a project or contract basis rather than building an entire team from scratch. An experienced developer who has shipped spaCy pipelines or fine tuned Hugging Face models before can usually spot the wrong approach in a planning meeting, before a single line of code is written. If your team is weighing this decision and does not have the in-house experience to move fast on either path, bringing in developers who already know both ecosystems is often the quicker and cheaper route than learning everything from documentation alone.
This also matters after launch, not just during the build. A model that performed well on day one can quietly lose accuracy over months as customer language shifts, new products get added, or slang changes. Someone needs to watch for that drift, retrain the model on fresh examples, and redeploy it without breaking the service in the process. Teams that budget for this ongoing care, rather than treating an NLP feature as a one time build, tend to see far better results two or three years down the line.
Conclusion
There is no single, permanent answer to which is better spaCy or Hugging Face, and treating this like a scoreboard competition misses the point of both tools. spaCy earns its place in production systems that need speed, structure, and low maintenance. Hugging Face earns its place in projects that need the newest models, deep customization, or generative capability. Many mature NLP systems end up using both, spaCy for the everyday linguistic work and Hugging Face for the harder, model heavy parts. Start from your actual task, your team's skills, and your hardware budget, and the right answer usually becomes clear well before you write your first line of code.
With a love for connecting with people and a flair for communication, Prachi's expertise in digital marketing is unmatched. Her strategic approach to campaigns ensures our brand's story reaches far and wide, making an impact on the lives of countless individuals.
Yes, and it is a common setup. The spacy-transformers extension lets you load a Hugging Face model as one component inside a spaCy pipeline. You get spaCy's clean structure for prediction and training, while the transformer underneath supplies stronger accuracy. Many production systems that started with plain spaCy add this layer once accuracy needs grow.
spaCy usually fits small teams better since it needs less specialized knowledge and runs on ordinary CPU servers. A 2 or 3 person team can ship a feature within days. Many founders researching the best NLP framework for AI development start with spaCy, then add Hugging Face once a dedicated ML engineer joins the team.
Not always. Small distilled models can run acceptably on CPU for light traffic. But training or fine tuning any transformer model, and serving larger models at scale, is far faster and cheaper per request on a GPU. Cloud GPU instances remain the most common route for teams without in-house hardware.
spaCy has a gentler learning curve. Its documentation walks through common tasks step by step, and the API stays consistent whether you are tagging parts of speech or extracting entities. Hugging Face requires understanding tokenizers, model checkpoints, and training loops first, which takes longer without a machine learning background.
It covers both. The Model Hub includes small, efficient models for classic tasks like sentiment analysis and named entity recognition, not just large generative models. A team can pick a lightweight model for a simple task and reserve bigger models for jobs that genuinely need deeper language understanding.
 Back to Blog