Find exceptional developers at Hourlydeveloper. Get the expertise, solutions, and teamwork you need for success. Hire developers easily and boost your projects today!
Sentence Transformers Explained: The Engine Behind Semantic Search
Search a customer support page for the exact words "cancel my subscription" and sometimes nothing useful comes back, even though a page titled "How to end your membership" answers the question perfectly. That gap between what a person types and what a document actually says is the exact problem semantic search was built to close, and sentence transformers do most of the heavy lifting behind that fix.
This guide explains what sentence transformers are, how Sentence Transformers work for semantic search in plain language, and how to build semantic search with Sentence Transformers from scratch, even if you have never trained a machine learning model before. There is no dense math here and no unnecessary jargon, just a clear walkthrough of a technology that now sits quietly behind product search bars, support chatbots, and internal document systems at companies of every size.
By the end, you will understand the difference between keyword search and meaning based search, know which pretrained models to reach for, and have a working mental map for turning a plain text dataset into a searchable, meaning aware system.
What Is Semantic Search, Really?
Keyword search matches letters. Type "affordable laptop for coding" into a search bar built on old school keyword matching, and it looks for pages containing those exact words, or close variations of them. A product page titled "Budget friendly programming laptop" might be the perfect match, yet it never shows up because the words do not line up character for character.
Semantic search works differently. Instead of matching text, it matches meaning. It reads a sentence, converts it into a set of numbers that represents what the sentence is actually about, and compares that number set against other sentences that have gone through the same process. Two sentences that mean roughly the same thing end up with number sets that sit close together, even if they do not share a single word.
This is not a small technical detail. It is the difference between a search bar that frustrates users and one that feels like it actually understands what they are asking for.
Keyword Search vs Semantic Search
Aspect
Keyword Search
Semantic Search
What it matches
Exact words or word stems
Meaning and context
Handles synonyms
No
Yes
Handles typos and rewording
Poorly
Well
Works across languages
Rarely
Yes, with multilingual models
Speed at scale
Fast
Fast once embeddings are precomputed
Setup effort
Low
Moderate
The Problem With Older Search Methods
Before sentence transformers existed, developers leaned on methods like TF IDF and bag of words models to rank search results. These approaches count word frequency and weigh how rare or common a word is across a collection of documents. They work reasonably well for exact term matching, but they have no concept of meaning. The words "car" and "automobile" get treated as two completely unrelated tokens, even though a human reader knows they refer to the same thing.
Early attempts to fix this used word embeddings such as Word2Vec and GloVe, which gave individual words a meaningful numeric representation. That was progress, but sentences are more than a bag of individual word vectors averaged together. "The dog bit the man" and "the man bit the dog" contain the same words, yet mean something entirely different. A method that simply averages word vectors cannot tell these two sentences apart reliably, which made early sentence level search unreliable for anything beyond very simple matching.
What Are Sentence Transformers?
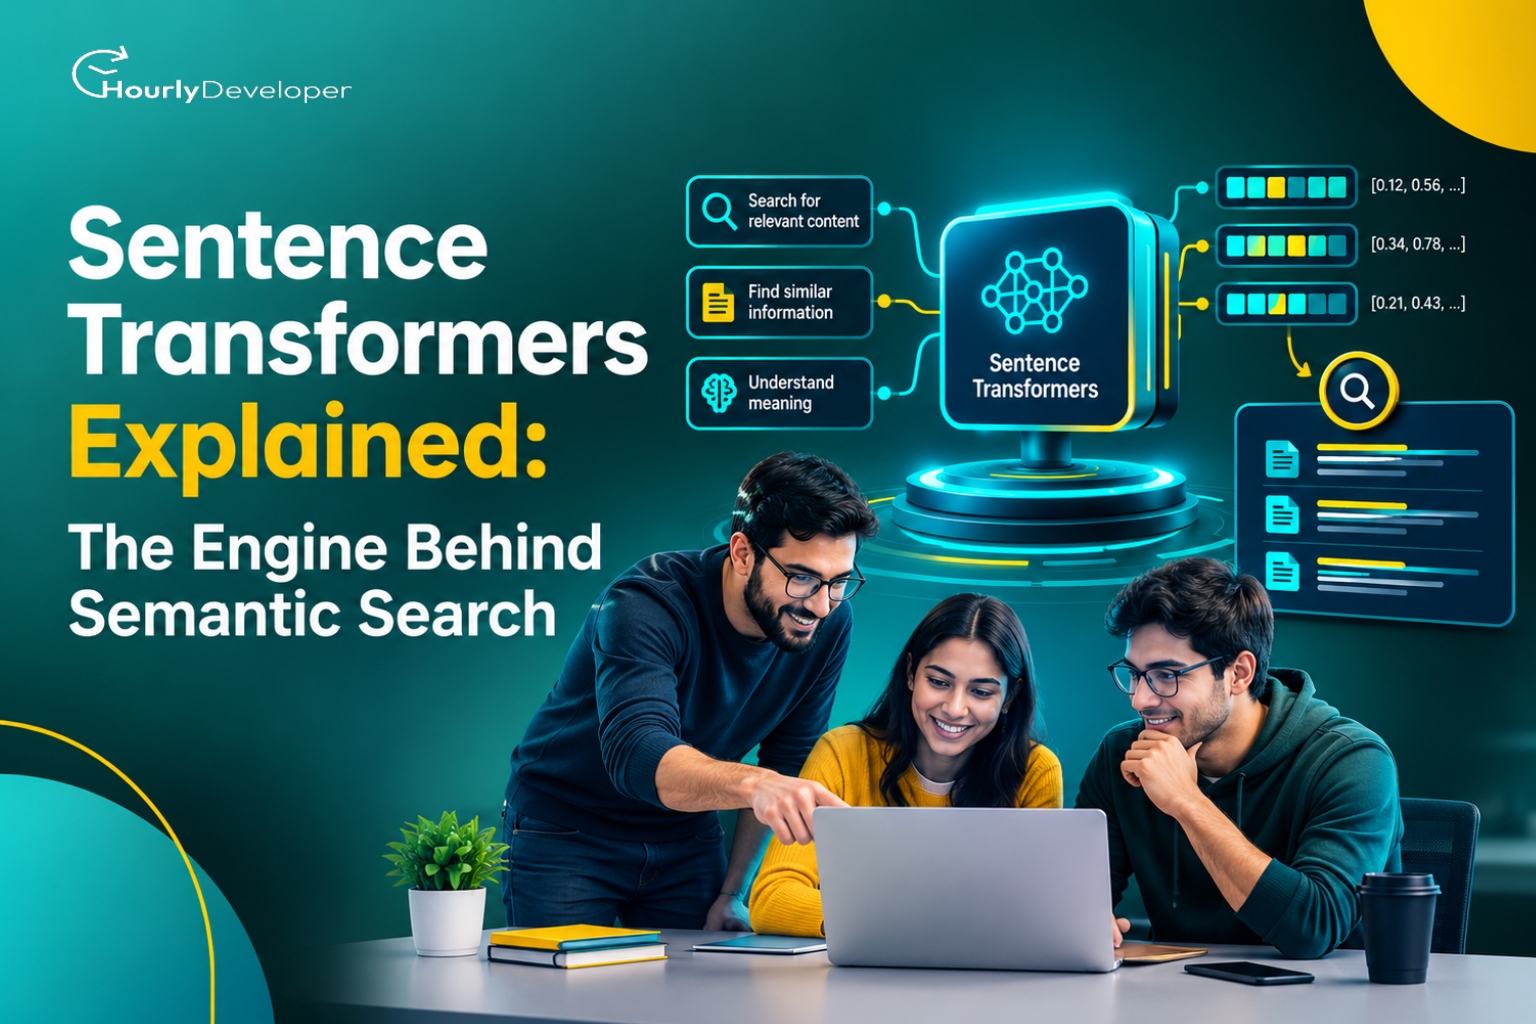
A sentence transformer is a machine learning model trained to take a full sentence, paragraph, or short document and turn it into a fixed length list of numbers called an embedding. Think of an embedding as a fingerprint for meaning. Two sentences with similar meaning produce fingerprints that sit close together in that numeric space. Two unrelated sentences produce fingerprints that sit far apart.
The idea grew out of BERT, a transformer model from Google that set new performance records on language tasks back in 2018. BERT was excellent at comparing two sentences directly, but it had a serious practical flaw. To find the most similar sentence out of a collection of 10,000 sentences using BERT, you would need to feed every possible pair into the model, one at a time. Researchers Nils Reimers and Iryna Gurevych calculated that this approach takes roughly 65 hours of computation for just 10,000 sentences, which makes it useless for any real search application.
In 2019, Reimers and Gurevych published Sentence BERT, commonly shortened to SBERT, and released it through the open source sentence transformers library. SBERT fixed the speed problem by training the model to produce a standalone embedding for each sentence independently, so sentences only need to be processed once and stored. Comparing two precomputed embeddings then takes a fraction of a millisecond using simple vector math, which turns that 65 hour job into a search that finishes in seconds.
Word Embeddings vs Sentence Embeddings
It helps to separate two ideas that often get mixed up. A word embedding represents a single word as a vector, without any sense of the words around it. A sentence embedding represents an entire sentence as one vector, built from the full context of every word in it working together.
This distinction matters because meaning frequently depends on word order and context, not just the words themselves. The word "bank" means something different in "river bank" versus "savings bank," and a sentence embedding captures that difference automatically because the transformer model reads the whole sentence before producing its output. A simple average of word vectors cannot make that distinction, which is exactly why sentence transformers replaced older averaging based methods for anything involving real semantic search.
How Sentence Transformers Work for Semantic Search
Here is the part that actually matters if you want to use this technology, not just read about it. How Sentence Transformers work for semantic search comes down to four steps that happen every time a sentence is processed.
Step 1, Tokenization. The input sentence gets broken into smaller pieces called tokens, which might be whole words or word fragments depending on the model's vocabulary. "Semantic search is useful" might become five or six tokens once punctuation and subword splits are accounted for.
Step 2, Transformer encoding. Each token passes through multiple layers of a transformer network, which builds a contextual representation for every token based on the entire sentence around it, not just the word in isolation.
Step 3, Pooling. The model now has one vector per token, but a search system needs a single vector for the whole sentence. A pooling operation combines all the token vectors into one fixed length vector, usually by averaging them, a method called mean pooling.
Step 4, Normalization and comparison. The resulting sentence vector, often 384, 512, or 768 numbers long depending on the model, gets normalized so it can be compared fairly against other vectors. Comparison happens using a formula called cosine similarity, which measures the angle between two vectors rather than their raw distance.
A short example makes this concrete. Encode the sentence "I love pizza" and the sentence "I enjoy eating pasta" using the same sentence transformer model, and their embeddings will land close together in the vector space, likely producing a cosine similarity score somewhere around 0.7 on a scale where 1.0 means identical meaning and 0 means completely unrelated. Encode "I love pizza" against "The stock market fell today" and the score drops close to 0, because the two sentences share almost nothing in meaning.
Pro Tip
Precompute and store embeddings for your entire dataset once, ahead of time. Only the incoming search query needs to be embedded live, which keeps response times fast even across millions of documents.
Understanding Pooling Strategies
Most modern sentence transformer models, including the popular MiniLM and MPNet based checkpoints, default to mean pooling because it tends to produce more stable, evenly weighted embeddings across sentences of different lengths.
Pooling Strategy Comparison
Pooling Method
How It Works
Best For
Mean Pooling
Averages every token vector in the sentence
General purpose semantic search, most sentence transformer models
CLS Token Pooling
Uses only the vector from a special classification token
Models specifically fine tuned to rely on that token
Max Pooling
Takes the highest value at each vector position across all tokens
Highlighting the single most dominant signal in short text
Why Cosine Similarity Is the Standard Measure
Cosine similarity looks at the direction two vectors point in, not how long they are. Picture two arrows drawn from the same starting point. If they point in almost the same direction, the angle between them is small, and the cosine similarity score sits close to 1. If they point in completely different directions, the score drops toward 0 or even into negative numbers.
This matters because sentence length can otherwise distort comparisons. A short sentence and a long sentence covering the same topic should still be recognized as similar, and cosine similarity handles that naturally because it ignores vector magnitude and focuses purely on direction, which corresponds to meaning in this context.
Popular Sentence Transformer Models You Should Know
Not every sentence transformer model is built the same way, and picking the right one affects both accuracy and cost. The table below covers models commonly used in production semantic search systems today.
For most teams starting out, all MiniLM L6 v2 is the practical default. It is small enough to run cheaply, fast enough for real time queries, and accurate enough for the majority of semantic search use cases. Teams that need higher precision, particularly for tasks like legal document search or medical record retrieval, typically move up to all mpnet base v2 once initial testing confirms the accuracy gain is worth the extra computation cost.
How Sentence Transformers Compare to Other Embedding Options
Sentence transformers are not the only way to generate text embeddings, and it is worth knowing what the alternatives look like before committing to one approach. Closed source options such as OpenAI's embedding models and Cohere's embedding endpoints deliver strong accuracy and require no infrastructure to host, but every request goes through a paid API and your text leaves your own systems in the process.
Open source sentence transformer models flip that tradeoff. You host the model yourself, whether on a server you control or through a cloud GPU instance, which means no per query fees once the infrastructure is running, full control over where your data lives, and the freedom to fine tune the model on your own content. The cost is a bit more setup work up front, which is exactly what the build steps later in this guide walk through.
Sentence Transformers vs Other Embedding Options
Option
Hosting
Cost Model
Data Privacy
Sentence Transformers (open source)
Self hosted
Compute cost only, no per query fee
Full control, data never leaves your systems
OpenAI embedding models
Managed API
Pay per token processed
Text is sent to a third party API
Cohere embedding models
Managed API
Pay per token processed
Text is sent to a third party API
Classic TF IDF or bag of words
Self hosted
Nearly free, minimal compute
Full control, but weak semantic accuracy
How to Evaluate Sentence Transformer Model Quality
Picking a model should not be a guess. The Massive Text Embedding Benchmark, known as MTEB, is a public leaderboard that scores sentence transformer and other embedding models across dozens of tasks, including retrieval, clustering, and classification. It is a reasonable starting point for narrowing down candidates before testing anything yourself.
That said, a benchmark score is a general signal, not a guarantee for your specific content. The most reliable evaluation method is building a small test set from your own data, perhaps 50 to 100 real queries paired with the document each query should correctly match, then running each candidate model against that set and measuring how often the correct document lands in the top few results. This kind of test usually takes less than a day and tells you far more than a leaderboard ranking alone.
Real World Applications of Semantic Search
Semantic search has moved well beyond research papers and now shows up across everyday products people use daily, often without users realizing a sentence transformer model is running quietly in the background. The list below covers the use cases that come up most often in real projects.
• Ecommerce product search: a shopper searching "warm jacket for winter hiking" finds relevant products even if the listing says "insulated outdoor coat" instead
• Customer support and help centers: support portals match a user's question to the right help article even when the exact wording is different
• Enterprise document search: large companies use semantic search to find contracts, policies, or reports scattered across thousands of internal files
• Retrieval augmented generation (RAG): AI chatbots use semantic search first to pull relevant context, then generate an answer grounded in that retrieved content
• Duplicate and near duplicate detection: platforms use sentence embeddings to catch reworded spam, plagiarism, or repeated support tickets
• Resume and job matching: recruiting platforms compare resume text against job descriptions based on meaning rather than exact keyword overlap
• Recommendation systems: streaming and content platforms cluster similar articles, products, or media using sentence embeddings as the similarity signal
How to Build Semantic Search With Sentence Transformers
This is where theory turns into something you can actually ship. How to build semantic search with Sentence Transformers generally follows five practical steps, whether you are building a small internal tool or a production search system.
Step 1: install the library and pick a model. The sentence transformers library installs with a single pip command, and it gives direct access to hundreds of pretrained models through the Hugging Face model hub. For most projects, starting with all MiniLM L6 v2 keeps setup fast and inference cheap.
Step 2: generate embeddings for your dataset. Every document, product description, FAQ answer, or support article in your collection gets passed through the model once, producing one embedding per item. This step runs offline and only needs to be repeated when your content actually changes.
Step 3: store the embeddings in a vector store. Storing raw vectors in a plain list works fine for a few thousand items, but production systems typically use a vector database such as FAISS, Pinecone, Milvus, Qdrant, or Chroma. These tools index embeddings so similarity search stays fast even across millions of records, using algorithms like approximate nearest neighbor search instead of comparing every vector one by one.
Step 4: Embed the incoming query and search. When a user types a search query, that single query gets converted into an embedding using the same model used for the dataset. This is the only embedding generated in real time, which keeps response latency low.
Step 5: rank results using cosine similarity. The query embedding gets compared against every stored embedding using cosine similarity, and the top scoring matches get returned as search results, usually the highest 5 to 20 matches depending on the interface.
A practical detail teams often skip on a first attempt is combining semantic search with simple metadata filters. A search for "laptop under $800" works far better when the price filter is applied directly in the vector database query rather than left entirely to the embedding model, since a price constraint is an exact numeric fact, not a matter of meaning. Most vector databases support this kind of filtered vector search natively.
A minimal working example looks like this in Python:
from sentence_transformers import SentenceTransformer, util
This short script alone answers a real question. It correctly ranks "How to reset your password" as the top match for "I forgot my login password," despite the two sentences sharing only one word.
Teams without in house machine learning experience often reach a point in this process where progress slows, usually around chunking strategy, vector database selection, or scaling past a few hundred thousand records. This is a common moment to hire Python developers who have specifically worked with embedding pipelines, since the difference between a working prototype and a production ready search system usually comes down to details like batching, caching, and index tuning that are easy to miss on a first pass.
Build Approach Comparison
Approach
Setup Time
Cost
Best For
DIY with Sentence Transformers and FAISS
Days
Low, mostly compute cost
Small to medium datasets, full control
Managed vector database (Pinecone, Qdrant Cloud)
Hours
Moderate, usage based pricing
Fast launch, less infrastructure work
Enterprise search platform (Elastic, Algolia with vector support)
Days to weeks
Higher, licensing plus infrastructure
Large companies needing hybrid search and support
Pro Tip
Break long documents into smaller chunks, typically 100 to 300 words each, before embedding them. A single embedding for a 5,000 word document tends to blur too many topics together, which hurts search accuracy. Chunking keeps each embedding focused on one clear idea.
Common Challenges and Practical Fixes
None of the challenges below are reasons to avoid semantic search, but knowing about them ahead of time saves real debugging time later. Most teams run into one or two of these within the first month of running a system in production.
• Domain specific vocabulary: general purpose models sometimes miss meaning in specialized fields like medicine, law, or finance. Fine tuning the model on domain text, even a modest dataset, usually closes most of the gap
• Long document handling: a single embedding cannot represent a very long document well. Chunking, as covered above, solves this in almost every case
• Scaling past millions of records: brute force comparison becomes too slow at large scale. Approximate nearest neighbor indexes inside vector databases solve this without a meaningful accuracy tradeoff
• Multilingual content: not every model handles multiple languages well. Models specifically trained for multilingual use, such as paraphrase multilingual MiniLM L12 v2, are built for exactly this situation
• Embedding drift after model updates: switching to a newer or different model means old embeddings are no longer directly comparable to new ones, so a full reembedding of the dataset is required after any model change
Market Snapshot: Why Companies Are Investing in Semantic Search
Semantic search is not a niche experiment anymore, it is infrastructure. The global vector database market, the storage layer that most production semantic search systems depend on, was valued at approximately $2.65 billion in 2025 and is projected to reach nearly $8.95 billion by 2030, a compound annual growth rate of roughly 27.5 percent according to MarketsandMarkets research. That growth is driven directly by companies adopting large language models, retrieval augmented generation, and AI powered search across ecommerce, customer support, and enterprise software.
For businesses evaluating whether this investment makes sense, the practical answer is simple. Any product with a search bar, a knowledge base, or a recommendation feed is a reasonable candidate for semantic search, and the underlying technology has become mature and inexpensive enough that smaller teams can adopt it without enterprise level budgets, though many still bring in an AI development company for the parts of the build that touch infrastructure and scaling.
Key Takeaways
Key Takeaways
- Sentence transformers convert full sentences into meaning based numeric vectors called embeddings
- How Sentence Transformers work for semantic search comes down to tokenization, transformer encoding, pooling, and cosine similarity comparison
- SBERT solved a real performance problem, cutting comparison time for 10,000 sentences from roughly 65 hours to a matter of seconds
- Mean pooling and cosine similarity are the standard combination used across most production systems today
- How to build semantic search with Sentence Transformers follows five steps: pick a model, generate embeddings, store them in a vector database, embed incoming queries, then rank by similarity
- Chunking long documents and choosing the right pretrained model matter more to accuracy than most teams initially expect
When You Might Need Expert Help
Building a semantic search prototype over a weekend is realistic for a small dataset. Running one reliably in production, across millions of records, multiple languages, and unpredictable query patterns, is a different problem entirely. This is usually the point where internal teams decide to hire Python developers with direct experience in embedding pipelines, vector databases, and model evaluation, rather than learning these lessons through trial and error on a live product.
An AI development company brings something a single hire often cannot: a team that has already built and scaled similar systems, knows which pretrained models hold up under real traffic, and can handle everything from data pipeline design to infrastructure and monitoring. Whether you need tohire Python developers for a focused embedding project or want an AI development companyto own the entire search system end to end, the right technical partner shortens the distance between a working prototype and a search feature your users actually trust.
Conclusion
Sentence transformers turned a slow, academic idea into something practical enough to power everyday search bars, support tools, and AI assistants. The technology is not complicated once it is broken into its real parts: convert text to meaning based vectors, store them efficiently, and compare them using cosine similarity. What separates a rough prototype from a search system users actually rely on is careful execution around chunking, model selection, and infrastructure choices covered throughout this guide.
The models themselves are free, well documented, and supported by an active open source community, which means the biggest barrier to getting started is rarely the technology itself. It is usually just deciding to run the first test.
If you are weighing whether to build this in house or bring in outside help, start small. Test a pretrained model like all MiniLM L6 v2 against a sample of your own content before committing to a full build. The results will tell you quickly whether semantic search is worth the investment for your specific use case.
Digital Marketing Manager: With a passion for data-driven strategies and an instinct for spotting trends, Radhika navigates the virtual realm with finesse. Her commitment to staying ahead of the curve ensures our brand's message reaches the right audience at the right time.
No. Many sentence transformer models are trained specifically for multilingual use, including options that cover more than 50 languages within a single model. A commonly used one, paraphrase multilingual MiniLM L12 v2, embeds a Spanish sentence and an English sentence into the very same vector space, so cross language semantic search works without needing a separate model for each language.
The models themselves are free and open source, so cost mainly comes from compute and storage. Small datasets under 100,000 items often run on a modest cloud server for a few dollars a month, while large scale systems with millions of records typically cost more once a managed vector database and higher search traffic are added into the setup.
Rarely by itself. Most production systems run hybrid search, pairing keyword matching for exact terms like product codes or serial numbers with semantic search for natural language queries. This combination catches cases semantic search alone can miss, such as searching for a specific model number where exact text matching still performs better than meaning based ranking.
Fine tuning a pretrained model on a focused dataset, such as a few thousand labeled sentence pairs from one industry, typically takes a few hours on a single GPU rather than days. Many teams skip fine tuning at launch entirely, since general purpose models already perform well enough for most early stage semantic search projects.
They work, but accuracy can drop for very short input since there is less context for the model to draw on. Search systems handling mostly single word or two word queries sometimes pair semantic search with traditional keyword matching, or slightly expand short queries before embedding them, to keep results reliable in that specific scenario.
 Back to Blog