Find exceptional developers at Hourlydeveloper. Get the expertise, solutions, and teamwork you need for success. Hire developers easily and boost your projects today!
Build Your Remote Team Now !
RAG vs Semantic Search: The Real Difference for AI Apps
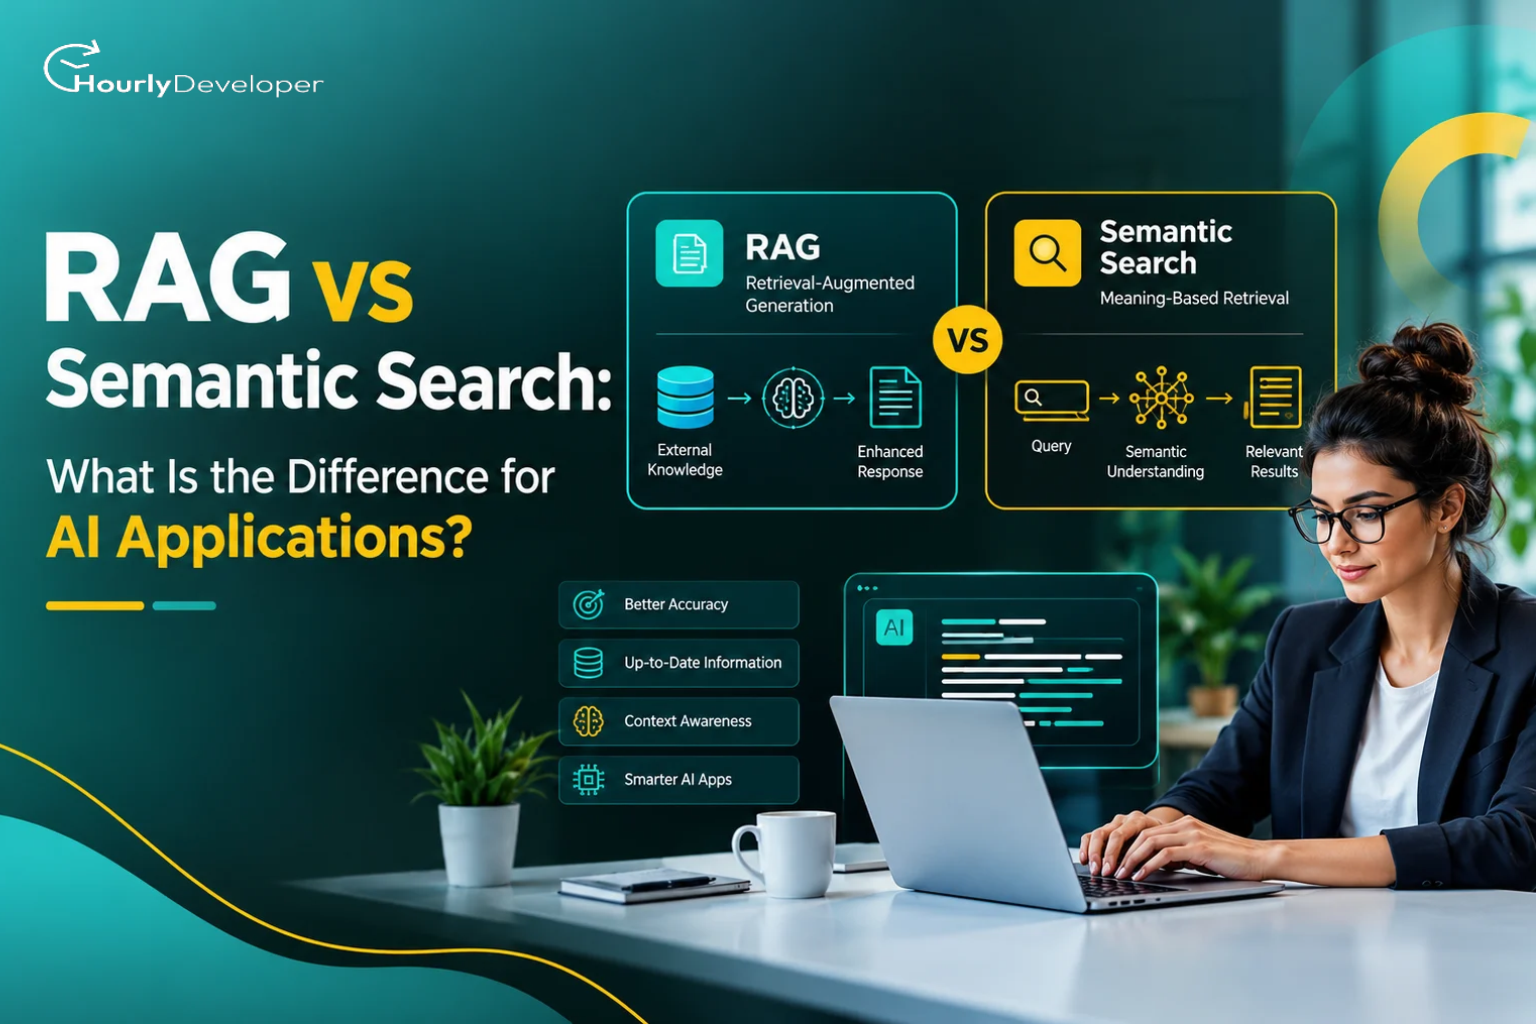
RAG vs Semantic Search: What Is the Difference for AI Applications?
A support lead at a mid-sized software company ran a small test with two new internal tools. She typed the same question into both: "Can a customer on the yearly plan get a refund after 45 days?"
The first tool gave her five documents. The top result was the current refund policy, which was the right document. She still had to open it, scroll to section four, and read the fine print herself.
The second tool gave her a neat, friendly paragraph. It said yes, refunds were allowed within 60 days. That sounded great, except the 60-day rule had been replaced six months earlier. The tool had picked up an old policy file that nobody had deleted.
The first tool was semantic search. The second was RAG. Both were technically working, and both had a problem. The gap between them is what this article is about.
Anyone planning an AI feature will run into these two terms quickly. People often use them as if they mean the same thing. They don't. One finds information. The other finds information and then writes an answer from it. That extra step changes the cost, the speed, the risk, and the kind of mistakes you will run into.
The short answer
Semantic search takes your question and returns the most relevant pieces of content, ranked by meaning rather than by exact words. You get a list, and you read it.
RAG, short for retrieval-augmented generation, takes your question and runs a search like that in the background. It then hands the best results to a large language model (the kind of AI behind tools such as ChatGPT or Claude) and asks it to write an answer using that material. You get a written reply, ideally with links showing where the information came from.
So RAG usually has semantic search inside it. Many explanations skip this point, and it matters for almost everything that follows.
What semantic search actually does
Older search tools match words. Say you search "laptop won't turn on", and the help article is titled "Fixing power problems on notebooks". A keyword search may miss it completely, because the important words don't match.
Semantic search looks at meaning instead. It can tell that "laptop" and "notebook" are close and that "won't turn on" is about power.
How it works, in plain terms
The trick behind it is something called an embedding. An embedding is a long list of numbers that describes what a piece of text means. Think of it like map coordinates. Every sentence gets a spot on a huge map, and sentences with similar meanings sit near each other. "How do I reset my password?" and "I forgot my login details" land in the same neighborhood, even though they share almost no words.
A typical setup follows these steps:
1. Your documents are split into smaller pieces called chunks. A chunk might be a paragraph or a few hundred words.
2. An embedding model turns each chunk into its list of numbers.
3. Those numbers go into a vector database, which is a database built to find nearby points on that map quickly. Pinecone, Weaviate, Milvus, and the pgvector add-on for PostgreSQL are common choices.
4. When someone types a query, the query gets turned into numbers the same way.
5. The database returns the chunks sitting closest to the query.
There is no writing or summarizing involved. The output is a ranked list.
Where semantic search does well
It is fast. A well-built setup returns results in a fraction of a second, often in tens of milliseconds, even across millions of chunks. It is also cheaper to run than RAG, because no language model has to write a reply for every question.
It keeps people in charge, too. Users see the source documents directly, so the system has less room to put words in anyone's mouth. For product catalogues, legal research tools, internal document finders, job boards, and "related articles" sections, that is often exactly what you want. Plenty of AI search development work today comes down to this: swapping an old keyword search box for one that understands what people mean.
The weak spot is that it doesn't answer questions. If the answer is spread across three documents, the user has to find all three and put the pieces together.
What RAG actually does
RAG adds a writing step on top of the search step. The name gives you the order: retrieve first, then generate.
An open-book exam is a good way to picture it. A language model on its own is like a student answering from memory. It knows a lot, but its memory stops at a certain date, it has never seen your company's files, and when it isn't sure, it sometimes makes things up with total confidence. People call that last habit hallucination. RAG gives the student the textbook, already open to the right pages, and says, 'Answer using this.'
The RAG flow
1. A user asks a question.
2. The system searches your content, usually with semantic search and sometimes with keyword search alongside it.
3. The top few chunks, often somewhere between five and twenty, are placed into a prompt along with instructions such as "Answer using only the material below and cite your sources."
4. The language model reads that prompt and writes a reply.
5. The app shows the answer, ideally with links to the chunks it used.
The idea comes from a 2020 research paper by a team at Facebook AI Research, now Meta AI, working with university researchers. Since then it has become one of the standard ways companies build AI tools on top of their own data. Mostgenerative AI developmentprojects inside businesses, from support bots to HR assistants to sales helpers, end up using some version of it.
Why companies like it
RAG lets a general AI model talk about your specific information without retraining the model. Retraining, often called fine-tuning, is slow and expensive, and you would have to repeat it every time your documents changed. With RAG, you update the documents, refresh the index, and the answers change the next time someone asks.
It also makes answers checkable. If the reply cites "Refund Policy v4, section 2", a person can click through and confirm it.
This is why RAG development has turned into a speciality of its own. A basic demo can be running in the afternoon. Getting answers that people actually trust takes weeks of work on chunking, retrieval quality, prompts, and testing.
★ PRO TIP
Before building anything, write down 30 to 50 real questions your users ask, along with the correct answers. This small test set will tell you more about quality than any vendor demo. Run it again every time you change a setting, a prompt, or a model.
The part most people miss: RAG is built on search
RAG runs a search before it writes, so its answers can never be better than the search results it gets. If the retrieval step pulls the wrong chunks, the model will write a smooth, confident answer from the wrong material. That is exactly what happened with the refund question at the start.
This has a practical side for anyone planning a project. If your semantic search is weak, putting a language model on top won't fix it. It will hide the problem. A bad list of search results looks bad, and people notice. A bad RAG answer can read perfectly well, and people believe it.
So the real decision is rarely "search or RAG". It is closer to "Do we stop at search, or do we add a writing step on top of it?"
The main differences, one at a time
What the user gets
Semantic search gives a list of results. RAG gives a written answer. That sounds obvious, but it shapes the whole experience. With search, users do the reading and the thinking. With RAG, the system does that work, and users have to decide how far to trust it.
Speed
Semantic search is quick, usually well under a second. RAG adds a language model call, and the model writes its answer piece by piece. A typical RAG reply takes somewhere between one and several seconds, depending on the model, the length of the answer, and how much text goes into the prompt.
Cost
Search costs are mostly storage plus the one-time cost of creating embeddings. Each query costs very little. RAG adds a model charge on every question, and that charge grows with the amount of retrieved text you send along. Sending twenty long chunks per question costs noticeably more than sending five short ones. At a few hundred questions a day, this barely matters. At a few million, it becomes a line item your finance team will ask about.
The kind of mistakes you see
Search tends to fail in plain sight. The right document isn't in the top results, and the user can tell. RAG can fail quietly. It might mix up two policies, rely on an outdated source, or fill a gap with something that sounds reasonable. Those errors are harder to catch, which is why testing and monitoring matter more for RAG than for search.
Trust and traceability
With search, the source is the result, so you always know where information came from. With RAG, you have to design that in: show citations, link to the exact passage, and instruct the model to say "I don't know" when the material doesn't cover the question.
Ongoing upkeep
Both need content that is clean and current. RAG adds more to look after: prompts, model choice, rules for how answers should read, and checks that private data isn't slipping into replies. Anyone budgeting forRAG developmentshould plan for this upkeep, not only the first build.
Side-by-side comparison
Factor
Semantic search
RAG
What it returns
A ranked list of documents or passages
A written answer, ideally with sources
Main parts
Embedding model, vector database, ranking
Everything in semantic search, plus a language model and prompts
Typical response time
Tens to hundreds of milliseconds
Roughly 1 to 10 seconds
Cost per query
Low
Higher, and grows with prompt length and model choice
Who does the reading
The user
The system
How it usually fails
Wrong or missing results, easy to spot
Confident but wrong answers, harder to spot
Showing sources
Built in
Has to be designed (citations)
Questions spread across many documents
Weak, the user has to combine results
Strong, if retrieval finds every piece
Best for
Finding documents, products, or records
Answering questions, summarizing, drafting
Setup effort
Moderate
Higher
By the numbers: how fast RAG is growing
Market research firms agree that RAG is growing quickly. They disagree, sometimes by a wide margin, on how big it will get.
Source (date)
What it reports
MarketsandMarkets (Oct 2025)
RAG market at USD 1.94 billion in 2025, projected to reach USD 9.86 billion by 2030 (38.4% yearly growth)
Mordor Intelligence (Aug 2025)
USD 1.92 billion in 2025, projected at USD 10.2 billion by 2030 (39.66% yearly growth)
Precedence Research (Dec 2025)
USD 1.85 billion in 2025, projected at USD 67.42 billion by 2034 (49.12% yearly growth)
Menlo Ventures, 2024 enterprise report (Nov 2024)
51% of enterprises surveyed were using RAG as an AI design pattern, up from 31% the year before
Menlo Ventures, 2025 enterprise report (Dec 2025)
Prompt design is still the most common technique, with RAG next; 76% of enterprise AI use cases were bought rather than built, up from 53%
The starting figures line up closely, with every firm putting 2025 at around USD 2 billion. The long-range forecasts spread much further apart, mostly because each firm defines the market differently and projects over a different number of years. Treat any single forecast as a sense of direction rather than a fact.
The Menlo figure on buying versus building is worth a second look. Most large companies now buy AI tools or bring in outside help instead of building everything themselves. For a smaller business, that often means working with an AI development companyfor the first version and keeping a lean internal team for upkeep.
Where things break: the hard parts
The real test comes when data is incomplete, messy, fast-moving, or huge.
1. Data gaps
Sometimes the answer simply isn't in your documents. Semantic search handles this in a way that is honest but unhelpful: it still returns the closest results, even when they aren't relevant. The nearest point on the map is still the nearest, even if it is far away. Someone searching "parental leave policy for contractors" may get the employee parental leave policy at the top, which is related but wrong for them.
RAG makes this riskier. Given loosely related chunks, a language model may stitch together an answer anyway. A few habits help:
▪ Set a minimum relevance score. If no chunk scores above it, the system says "I couldn't find this" instead of guessing.
▪ Tell the model plainly, in its instructions, to say so when the material doesn't answer the question.
▪ Keep a log of every "no answer" case. That log becomes a to-do list for whoever manages your content, because it shows exactly which documents are missing.
Gaps also come from how content gets split. If a table is cut in half during chunking, or a policy's exceptions sit in a footnote on another page, retrieval may only find half the story. Careful AI search development spends a lot of time on this unglamorous step: splitting by headings, keeping tables whole, and attaching a title and date to every chunk so it still makes sense when read alone.
2. Conflicting signals
Company data often disagrees with itself. There is the 2023 pricing sheet and the 2025 one. The sales deck says one thing and the contract template says another. A chat thread from last week contradicts the wiki.
Semantic search just shows both. The user sees two documents and has to judge, which in some ways is the safer outcome.
RAG has to pick. A language model given two conflicting passages might choose one without saying why, blend them into something that matches neither, or mention both without saying which is current. Ways to deal with this:
▪ Store metadata with every chunk. Metadata is simply information about the information, such as the date, the owner, the version number, and whether it is a draft or approved.
▪ Filter or rank by that metadata before the model sees anything. Approved content beats drafts. Newer content beats older content, unless a rule says otherwise.
▪ Ask the model to point out conflicts openly, for example: "Two sources disagree. The 2025 policy says X, while an older document says Y."
▪Set a ranking of sources. An official policy page should carry more weight than a chat message.
This is one of the places where generative AI development turns out to be more about data rules than about AI. The model can only be as consistent as the material it receives.
3. Real-time decisions
Some apps need answers based on what is true right now: stock levels, order status, flight delays, account balances. Both approaches struggle if all they have is an index that was built last night.
The usual fix is to split the work. Slow-changing content, like policies, guides, and product descriptions, lives in the search index. Fast-changing facts get pulled live from the source system when the question comes in, through an API call (a direct request to another piece of software). A shopping assistant might use semantic search to find "waterproof hiking boots under $150," then check live stock before recommending a pair.
Time limits matter as well. If a RAG answer has to appear inside a live chat or on a call-center agent's screen, every extra second counts. Teams often route simple questions to a smaller, faster model and save the bigger model for harder ones. For pure lookups, like "which meeting room has the projector?", plain search with the right line highlighted can be faster and just as useful as a generated answer. Knowing when not to call a language model at all is an underrated skill, and it is worth asking about when youhire AI developers.
4. Exceptions and edge cases
Certain problems show up in almost every project.
▪ Exact codes and names trip up semantic search more than people expect. To an embedding model, "Error E-4012" and "Error E-4021" look almost the same. That is why most serious systems use hybrid search, which runs keyword search and semantic search together and merges the results.
▪ Negative phrasing is another weak spot. A search for "laptops without touchscreens" can bring up touchscreen laptops, because the two ideas sit close together on the meaning map. Filters on product details work better here than clever wording.
▪ Very short queries give the system little to work with. A single word like "leave" could mean time off, quitting, or something else entirely. Showing a few options or asking a follow-up question is better than guessing.
▪ Mixed languages are common in many countries, such as Hindi and English blended together (often called Hinglish). Pick an embedding model that handles the languages your users actually type in, and test it with real messages.
▪ Permissions need care. If a junior employee searches and the system pulls a chunk from confidential board notes, search will show it to them and RAG might quote it in the answer. Access rules have to be applied during retrieval, before anything reaches the model or the screen.
▪ Questions that need counting or math are a poor fit. "How many customers asked for refunds in Q3?" is not a search problem. RAG only sees a handful of chunks, not the whole dataset, so any number it gives is a guess. Questions like that belong with a proper database query.
5. Behavior under pressure and at scale
A setup that works nicely with 5,000 documents and 50 users can wobble at 5 million documents and 50,000 users.
On the search side, vector databases use shortcuts to stay fast as they grow. The most common is approximate nearest neighbor search, which checks the most likely areas of the map instead of every single point. It is much faster but can now and then miss the true best match. Most teams accept a small drop in accuracy in exchange for a big gain in speed. Measure that trade on your own data instead of assuming it is fine.
Updating the index also gets harder. Switching to a new embedding model means converting every chunk again, which can take hours or days across millions of chunks and costs real money. Numbers from different embedding models don't mix, so you can't switch halfway through. Plan for a full rebuild, and run the old and new indexes side by side until the new one proves itself.
On the RAG side, the bottleneck is usually the language model. Model providers set rate limits, which cap how many requests you can send per minute. During a traffic spike, say a product launch or an outage when everyone rushes to the help bot at once, requests pile up, answers slow down, and some fail outright. Sensible designs plan for that:
▪ Fall back to plain search results when the model is slow or unavailable, so users still get something useful.
▪ Store answers to repeated questions so they don't need a fresh model call.
▪ Cap how much text goes into each prompt, which also keeps costs predictable.
▪ Track answer quality over time, not only whether the system is up. A tool can stay online while its answers slowly get worse.
That last point catches many teams off guard. As a knowledge base grows, more near-duplicate chunks compete for the top spots, and retrieval that was sharp at launch can get muddy a year later. Teams doing RAG developmentat scale usually add a step called re-ranking, where a more careful model reorders the top 50 or so results before the best few are passed along. It adds a little time and cost, and it often makes a clear difference to answer quality.
★ PRO TIP
If your RAG tool seems less accurate than it was at launch, check retrieval before blaming the model. Look at which chunks were pulled for the bad answers. More often than not, the wrong material went in.
Which one should you use?
If your situation looks like this
A sensible starting point
Users want to find a specific document, product, or record
Semantic search
Users want a direct answer to a question
RAG
Answers carry legal, medical, or financial risk
Semantic search, or RAG with strict citations and human review
Your content is small, messy, or often out of date
Clean the content first, then start with search
Queries include lots of codes, product numbers, or names
Hybrid search (keyword plus semantic)
Answers depend on live data
Either one, plus live lookups from the source system
Cost per query must stay very low at high volume
Semantic search, with RAG only for selected tasks
Staff need summaries across many long documents
RAG
Plenty of teams end up using both. Search powers the main box, and a "get an answer" button runs RAG on the same results. People who want to read the documents can, and people who want the short version get it.
Here is a simple test. Picture a sharp new hire with access to all the files. If they could answer the question in a few sentences after reading a couple of pages, RAG is a good fit. If they would just hand over the right folder, search is enough.
Building it: people, budget, and partners
Whichever path you pick, the AI model is only one piece of the job. Most of the effort goes into pulling content out of drives, wikis, and old PDFs, cleaning it, tuning retrieval, and applying permissions.
A small startup can usually get a working semantic search prototype running in a week or two with one experienced developer. A RAG system that a whole company depends on tends to take a small team a few months. The data cleanup, testing, and permission work take most of that time, not the AI itself.
If you plan tohire AI developers, look past the demo. Ask how they would measure retrieval quality, how they would handle two conflicting documents, and what happens when the model provider goes down. People who have shipped these systems answer with specifics.
Bringing in an AI development company is the other common route. Before you sign, ask a few direct questions. Can they share a test set and accuracy results from a past project, not just a live demo? How do they handle document permissions? What does support look like after launch, and who owns it? Will you own the index, the prompts, and the code? How do they keep costs steady as usage grows?
A good partner should also be willing to tell you when you don't need RAG at all. If a vendor pushes a generative answer engine for a problem that a better search box would solve, take note. The same goes for an AI search development proposal that skips hybrid search when your users type product codes all day.
KEY TAKEAWAYS
✔ Semantic search finds content by meaning and gives you a list. RAG finds content and then writes an answer from it.
✔ RAG depends on search. Weak retrieval leads to confident, wrong answers.
✔ Search is faster and cheaper per question. RAG is slower and costs more, but saves people reading time.
✔ Plan for missing data, conflicting documents, live data, permissions, and traffic spikes from the start.
✔ Many good products use both: search for finding things, RAG for answering questions.
Wrapping up
Go back to the support lead and her refund question. The search tool was accurate but left her to do the reading. The RAG tool did the reading but trusted a stale file. Neither result was a reason to drop the technology. Both pointed to the same fix: clean up the content, give every document a date and a status, and make the system show its sources.
That is the plain version of RAG vs semantic search. Semantic search is the foundation, and it finds things by meaning. RAG sits on top and turns what was found into an answer. Pick search when people need to find information and judge it for themselves. Pick RAG when they need a clear answer quickly and you can back it with good data and citations. Pick both when your users include both kinds of people, which they usually do.
If you are starting a generative AI developmentproject, start small: one team, one set of documents, a written test set, and a clear plan for what the system should do when it doesn't know. That groundwork will decide how well the finished product holds up far more than the choice of model.
Nainesh Pandya, our astute Director, navigates our team toward unprecedented success. With a fervent dedication to innovation and a sharp business acumen, Nainesh propels our company forward with resolute determination. His strategic foresight and compassionate guidance motivate us to scale new heights collaboratively.
Neither is better across the board. They solve different problems. Semantic search is the better choice when people need to find and review documents themselves. RAG is the better choice when people want a direct answer and your content is clean enough to support one. Many products use both side by side.
Yes. The "retrieval" part can be keyword search, a regular database query, an API call, or a mix of these. Vector databases are popular because they make meaning-based search fast, but they are not required. For a very small set of documents, some teams skip search entirely and place the whole text into the prompt. Good RAG development starts by asking which retrieval method suits your data, not by picking a tool first.
No. It cuts them down a lot because the model works from your material instead of its memory, but it can still misread a passage, combine two sources wrongly, or fill a gap with a guess. Citations, relevance thresholds, clear "I don't know" instructions, and regular testing with real questions are what keep errors low.
A simple semantic search prototype can be ready in one to two weeks. A production RAG system usually takes a few months, mostly because of data cleanup, permissions, and testing. Ongoing costs include hosting, model charges on every question, and occasional re-indexing. When you hire AI developers or ask for quotes, request an estimate of monthly running costs at your expected usage, not only the build price.
Watch for warning signs: many duplicate or outdated versions of the same document, files with no dates or owners, scanned PDFs that contain images instead of real text, and unclear rules about who can see what. If several of these apply, spend time on cleanup first. A good AI development company will usually begin with a short audit of your content before promising anything about accuracy.
 Back to Blog