Find exceptional developers at Hourlydeveloper. Get the expertise, solutions, and teamwork you need for success. Hire developers easily and boost your projects today!
Build Your Remote Team Now !
How to Integrate OpenAI's API Into Your Business App
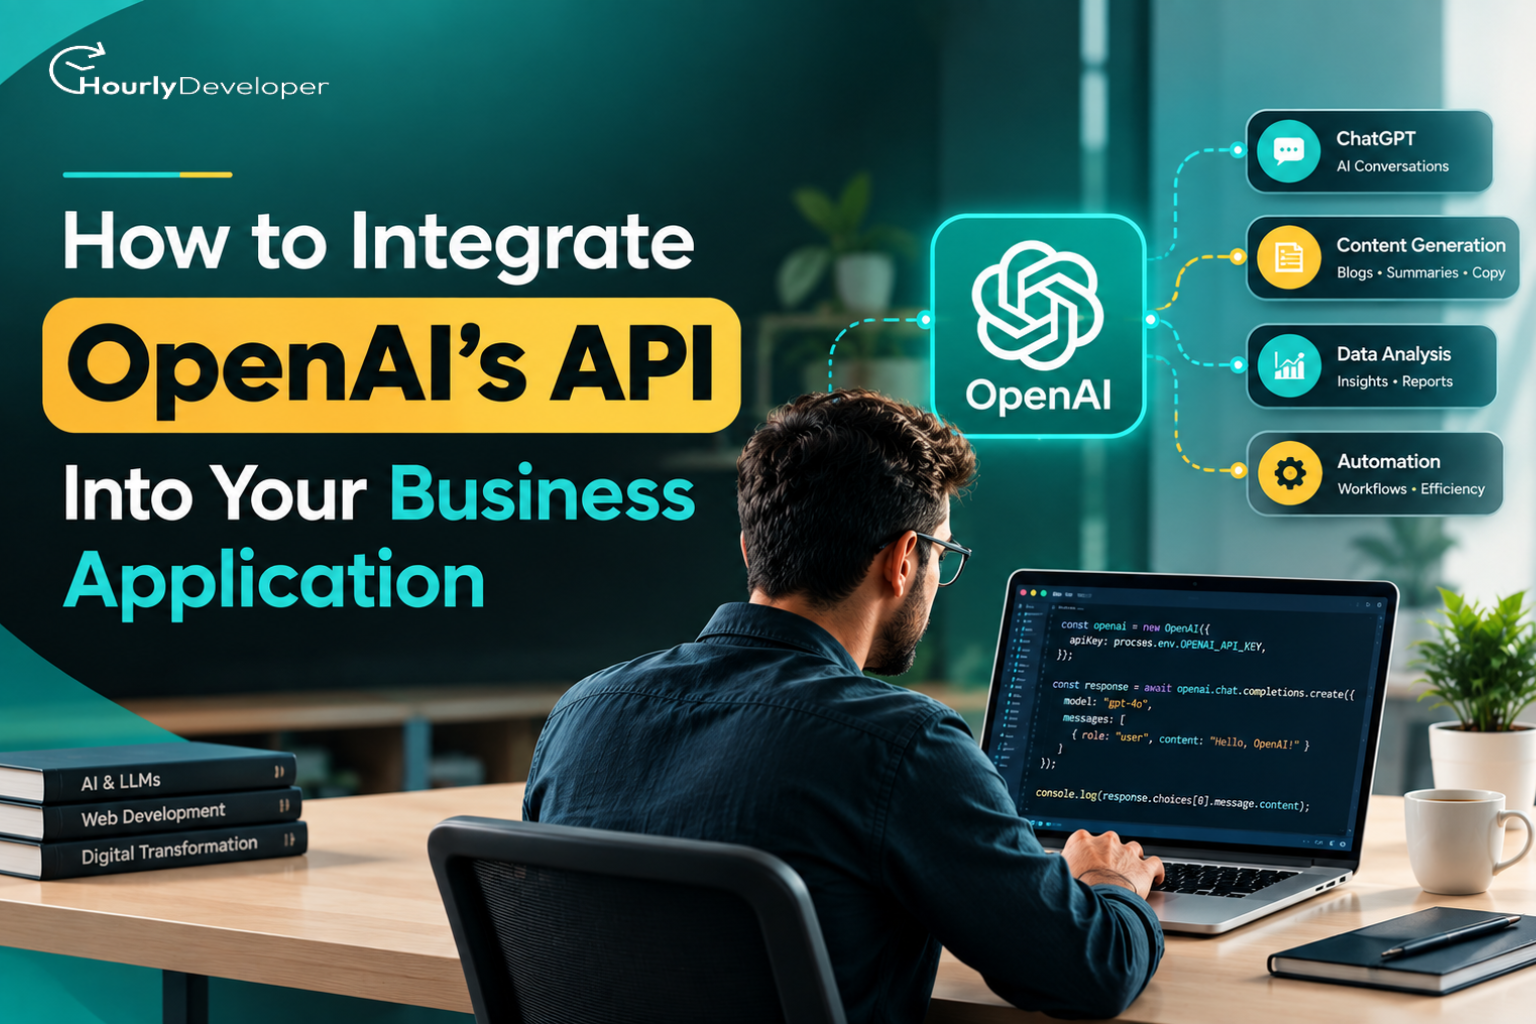
How to Integrate OpenAI's API Into Your Business Application
A few years ago, adding a smart feature to a business app meant hiring a data science team and spending months on a model that might not even work in the end. That is not where things stand anymore. A small team, sometimes one developer, can wire up a chat feature, a document summarizer, or a support assistant in an afternoon, because the model itself already exists somewhere else. You are not building intelligence from scratch. You are calling it.
This is a plain-language walkthrough of how to integrate OpenAI API into a business application - what the technology actually does, where it fits, where it does not, and what tends to go wrong once real customers and real data show up. If you are a founder scoping a feature, a product manager writing a spec, or a developer who has just been handed this task, this should get you unstuck.
Let us start with what you are actually working with, because a lot of confusion at the start comes from treating "AI" as one single thing.
OpenAI's API is a service you call over the internet, the same way you would call a payments API or a mapping API. You send it text, or an image, or audio, it sends a response back, and you pay for what you use. There is no installation, no server room, no model to train from zero. The heavy machinery sits on OpenAI's own servers, not yours.
Under that simple description sit a handful of separate tools, each suited to a different job:
● Chat and text models (the GPT family) - take a prompt and generate text back. Good for writing, answering questions, summarizing, sorting text into categories, and holding a conversation.
● Function calling and structured outputs - instead of replying only in prose, the model can hand back data in a fixed shape, say a JSON object with a customer's name, order number, and issue type, so your code can act on it directly.
● Embeddings – a way to turn text into a list of numbers that captures its meaning. Similar sentences produce similar numbers, which is the backbone of search and recommendation features.
● Vision – the model can look at an image, describe it, read text out of it, or answer questions about what is in it.
● Whisper (speech-to-text) and text-to-speech - turning voice into text and back again.
● Fine-tuning – training the model further on your own examples so it answers in a particular style or format more reliably.
● Assistants and agent tooling - giving the model access to files, a code interpreter, and outside tools, so it can work through a multi-step task instead of answering one question and stopping.
None of this needs a computer science degree to use. It needs an API key, a bit of code to send requests, and a clear idea of what job you actually want done. Teams that build AI applications using OpenAI API rarely train a single model of their own - the training work has already been done for you, at a scale almost no individual company could afford to repeat.
You will also see several model names when you sign up, and it helps to know roughly what they are for before you pick one. The larger, general-purpose models (the GPT-4 family and its newer versions) handle broad tasks well - writing, answering open-ended questions, holding a conversation. Smaller, cheaper versions of the same family exist for high-volume, simple jobs like tagging a support ticket or checking whether a message is spam. Then there is a separate line of "reasoning" models, built to work through multi-step problems more carefully, such as debugging code or working through a contract clause by clause - slower and more expensive, but noticeably better at tasks with several logical steps. Picking between them is less about which is "best" and more about matching the model's strength to the job at hand.
Which business apps actually benefit
Not every product needs this, and it is worth being honest about that before a whole sprint gets spent on it. Looking at where businesses build AI applications using OpenAI API and actually see results, the pattern usually falls into a few buckets:
● Customer support - a chat widget that answers common questions from your help docs, and hands off to a human the moment it is unsure.
● Internal knowledge search - staff ask a question in plain English instead of digging through a wiki or a shared drive.
● Content and drafting tools - marketing copy, product descriptions, first-draft emails, meeting notes turned into a short summary.
● Data entry and classification - reading an invoice, a support ticket, or a form, and pulling out the fields a person would otherwise type in by hand.
● Developer tools - code review comments, test generation, or an in-app assistant that explains what a feature does.
● Personalization - recommending products or content based on what a customer has said or browsed, described in plain language rather than a rigid rules engine.
The common thread is language in, language or structured data out. If the problem can be described as "read this, then tell me that," there is a good chance the API can help. If the problem is closer to "predict next month's revenue from ten years of transaction history," this is not really the right tool - that is a job for a more traditional forecasting model, not a language model.
Security and data handling basics
Before any of this touches real customer data, a few basics are worth settling, because they are much harder to retrofit than to plan for up front:
● Decide what you are allowed to send. Personal details, payment information, and health data usually need masking, removal, or a separate compliance review before they go anywhere near a prompt.
● Check your data retention settings on the OpenAI account. Business accounts can typically opt out of having request data used for model training, which matters for most commercial contracts.
● Keep an access log of who can view or change the API key and the prompts in production - treat it the same way you would treat access to a production database.
● If you operate in a regulated industry, get your compliance or legal team to sign off on the data flow before launch, not after a customer asks where their data went.
None of this is unusual by software standards. It is the same due diligence you would apply to any third-party service that touches customer information - it just gets skipped more often here because the feature feels experimental at first.
Who actually builds this: the real decision
Here is the part most integration guides skip. Calling the API is the easy fifth of the work. Deciding who does the work, and how it fits into your existing systems, is what actually determines whether the project reaches real customers or stalls as a demo.
Broadly, a business has three routes open to it.
1. Your existing developers pick it up
If you already have a development team, this is often the first instinct, and it can work well for a simple, contained feature like a support chatbot or a summarizer. The catch is that most in-house teams have never built with a language model before, and the failure modes are different from ordinary software. A model does not throw a clean error message when it is wrong - it gives you a confident, plausible-sounding wrong answer instead. That takes some getting used to.
2. You hire AI developers directly, freelance or on contract
This works well when you need a specific skill for a specific window of time - say, three months to build and ship one feature. You get someone who has already made the mistakes you are about to make, without a long-term commitment. The trade-off is continuity: once the contract ends, if something breaks or you want to extend the feature, you may be starting over with someone new who has to relearn your codebase from scratch. Businesses that hire AI developers this way should budget time for proper handover documentation, or the knowledge simply walks out the door with the contractor.
3. You bring in an AI development company
For anything beyond a single feature - several integrations, ongoing maintenance, or a product where AI sits at the center rather than as a bolt-on - working with an AI development company usually pays for itself. An established AI development company has already dealt with rate limits, runaway costs, and content-safety edge cases across other clients, so you are not the one discovering those problems for the first time, on your own customers. The trade-off is cost, and in some cases a little less day-to-day visibility into the work than an in-house hire would give you.
There is no universally right answer here. A five-person startup validating an idea should probably not hire AI developers on year-long contracts before it even knows the feature will stick. A two-hundred-person company adding AI across six products should probably not ask two backend engineers to figure it all out in their spare time either. Match the option to the size and permanence of what you are actually building.
The three approaches, side by side
Approach
Best for
Speed to launch
Ongoing cost
Risk
In-house team
Simple, contained features; teams that already know the codebase
Slower - learning curve
Lower ongoing cost, higher hidden cost from rework
A mid-sized online retailer we can use as a stand-in wanted to cut down on repetitive "where is my order" and "how do I return this" emails. The in-house team had never worked with a language model before, so the business chose to hire AI developerson a three-month contract for the first version, with the plan to bring maintenance in-house afterward.
The contractor connected the model to the order database and the returns policy document, capped responses to those two topics, and built a clear handoff to a human agent for anything else. The first version launched to 10% of support traffic. It handled about six out of ten incoming questions without a human touching them, and the handover documentation meant the in-house team could take over bug fixes once the contract ended. Nothing about that project needed an in-house data science hire - it needed a well-scoped feature, clean handoff design, and someone who had built one of these before.
How to integrate OpenAI API into a business application: the steps
With the decision made on who is doing the work, here is what the actual build looks like. This is the sequence we would walk through with a client, simplified so it makes sense even if you have never touched an API before.
● Get specific about the one job the feature should do. Not "add AI to the app," but something narrower, like "answer shipping questions using our returns policy" or "summarize a support ticket in one line for the agent dashboard."
● Get API access. Create an account on OpenAI's platform, generate an API key, and set a spending limit straight away - this single step prevents most of the horror stories about surprise bills.
● Pick the right model for the job. Not every task needs the most powerful, and most expensive, model available. A ticket classifier can often run on a smaller, cheaper model; a customer-facing writing assistant usually needs a stronger one.
● Write and test the prompt separately from the code. Before wiring anything into your app, test the instructions in a simple playground and get the wording right first. It is far cheaper to fix a prompt than to fix a shipped feature.
● Connect it to your own data. The API knows nothing about your business by default. If you want answers based on your policies, product catalog, or past tickets, feed that in yourself - directly in the prompt for small amounts of text, or through a search step that pulls the most relevant snippets first for larger amounts.
● Build the code that sends and receives requests. This is a standard call from your backend - Node, Python, .NET, Java, whatever you already use. Keep the API key on your server; never ship it inside code that runs in a user's browser.
● Decide what happens when the model cannot help. Every real deployment needs a fallback - a handoff to a human, a "let me check on that" message, or a clarifying question - rather than forcing an answer out of the model.
● Add logging before you add users. Record what was asked, what came back, how long it took, and what it cost. You will need this data in week two, not month six.
● Test with real, messy examples - typos, half-finished sentences, questions outside the scope you designed for. This is where most of the gaps show up.
● Launch small, watch closely, then expand. Start with one team, one use case, or one slice of customers, and widen it once you have seen a week or two of real usage.
None of these steps need deep machine learning knowledge. They need the same discipline as shipping any other feature: clear scope, testing, logging, and a plan for when things go wrong.
The part nobody warns you about
This is the section most guides skip, and it is usually the actual reason a pilot stalls before it reaches production. A model that works beautifully in a demo with three test questions behaves differently once real customers, real data, and real load show up.
Data gaps
The model does not know your internal systems, your current stock levels, or anything that happened after its training data ends, unless you tell it. If a customer asks about an order placed yesterday, the model has no idea it exists - it will either say so, or worse, guess. The fix is to always pass current data into the request yourself, an order lookup, a database query, a document snippet, rather than trusting the model to already know it. If you cannot supply the data, the honest move is to have the app say "I do not have that information" instead of letting the model fill the gap with something that merely sounds right.
Conflicting signals
Ask the same question twice and you can get two answers that do not quite agree, especially if the documents you feed it are themselves inconsistent, an outdated policy page sitting next to a newer one, for example. Lower the model's "temperature" setting for tasks where consistency matters more than creativity - support answers, form filling, anything with a single right answer. And clean up the source documents you are feeding it; a model cannot resolve a contradiction that already exists in your own knowledge base.
Real-time decisions
Any feature making a live call to an outside API is only as fast and as reliable as that call. A slow response, a temporary outage, or a rate limit, a cap on how many requests you can send per minute, will happen eventually. Design for it up front: show a loading state, set a timeout, and have a plan for what the app does if the API does not respond within a couple of seconds, rather than leaving a user staring at a spinner.
Exceptions
Not every input follows the happy path. Someone will paste in something the content filters flag, submit a blank message, or ask something entirely outside what you built the feature for. Handle these cases on purpose rather than assuming the model will always cooperate - check for empty or malformed responses, catch errors the same way you would from any other outside service, and keep a plain-language message ready for when something breaks.
System behavior over time
A feature that behaves well on day one can drift. OpenAI updates its models from time to time, your own data changes, and usage patterns shift as more people rely on the feature. What worked for a hundred users a month may not hold at ten thousand. Review a sample of real conversations on a schedule, track cost per request, and re-test your prompts whenever a model update ships. Treat this as ongoing maintenance, not a one-time build that is finished at launch.
It also helps to decide, before launch, who owns this maintenance. A feature with no clear owner tends to keep working right up until it quietly stops, and nobody notices until a customer complains. Whether that owner is someone in-house, a contractor you already hire AI developers from, or an AI development company on a support retainer, put a name against it.
Costs, and what the wider market is telling us
OpenAI's API is priced per token, roughly, per chunk of text processed, both what you send and what comes back. Costs vary a lot by model - a lightweight model built for simple tasks costs a fraction of what the most capable model costs, which is why picking the right model for each job matters as much for your budget as for how well the feature performs.
The wider market backs up why it is worth getting this right. Gartner has projected that more than 80% of enterprises will have used generative AI APIs or deployed AI-enabled applications in production by the end of 2026, up from under 5% in 2023 - one of the fastest adoption curves recorded for any enterprise technology. Separately, research from DreamFactory found that while 89% of developers now use generative AI in their daily work, only 24% actively design their systems with AI in mind, and 95% of IT leaders report running into integration issues along the way.
That gap between the two numbers is really the whole story of this guide. Adoption is happening fast. Doing it properly, with the data connections, error handling, and monitoring covered above, is the part still catching up. That gap is exactly where a good AI development company earns its fee, and exactly where an internal team or a contractor either does the unglamorous groundwork properly or ends up shipping a fragile pilot that never reaches real customers.
A rough rule of thumb worth keeping in mind while budgeting: for most business features, the API bill itself turns out to be a small slice of the total cost. The larger shares go to the people building the data connections, testing the prompts against real examples, and keeping an eye on the feature after it ships. Treat the API cost as the smallest line item, not the one to obsess over during planning.
Key takeaways
● OpenAI's API gives you access to language, vision, and speech models without training anything yourself - you are paying for usage, not infrastructure.
● The strongest use cases are "read this, tell me that" problems: support, search, summarizing, drafting, and classifying.
● Companies that build AI applications using OpenAI API rarely need to train a model of their own - the heavy lifting has already been done for them.
● Choosing between an in-house team, contractors you hire AI developers from, or a full AI development company depends mainly on the scope and permanence of what you are building.
● Most production failures come from unhandled edge cases, not from the model itself being wrong.
Pro tips
● Set a hard spending cap on your API account before you write a single line of code.
● Keep a running log of real user questions - it is the best source of test cases you will ever have.
● Lower the temperature setting for anything where a wrong or inconsistent answer causes real harm, billing, medical, or legal-adjacent content especially.
● Version your prompts like you version code - store them in your repository, not scattered across chat history.
● Build the "I do not know" response before you build the "I know" response. It matters more in practice than it sounds.
Closing thoughts
Integrating OpenAI's API into a business application is not really a machine learning project anymore. It is a software project that happens to call a very capable language model. The teams that get the most out of it treat it that way - clear scope, careful testing, honest fallback behavior, and continued attention after launch rather than only at the start.
If you are weighing whether to handle this internally, bring on a contractor, or ask for outside help, start with how permanent and how central the feature is to your product. A single support chatbot might be a fine first project for your own developers. A product where AI touches several workflows is usually worth a conversation with people who have done this before - whether that is a developer you hire directly or a full AI development company that can own the outcome from end to end.
Nainesh Pandya, our astute Director, navigates our team toward unprecedented success. With a fervent dedication to innovation and a sharp business acumen, Nainesh propels our company forward with resolute determination. His strategic foresight and compassionate guidance motivate us to scale new heights collaboratively.
You do not have to build everything yourself. Plenty of no-code and low-code platforms already sit on top of OpenAI's models. But if you want a feature that fits tightly into your existing app, your own database, and your own workflow, most teams end up choosing to build AI applications using OpenAI API directly, because off-the-shelf tools rarely match a specific business process out of the box.
It depends entirely on usage volume and which model you choose, but the API itself carries no upfront licensing fee - you pay only for what you use. In most projects, the bigger cost is development time: connecting your data, testing prompts, and building fallback handling. Budget for that as the main line item, not the API bill itself.
The model knows general knowledge up to its training cutoff, but nothing about your specific business unless you provide it. If you want accurate answers about your products, policies, or customer history, that information needs to be fed in at request time. This is usually the single most underestimated part of any project timeline - organizing and cleaning that data almost always takes longer than writing the code that calls the API.
For one well-defined feature with a fixed deadline, it is often practical to hire AI developers on a contract basis. For something that touches several parts of the product, needs ongoing support, or sits in a regulated industry, an AI development company usually offers more stability, since the team is not starting from zero on error handling, security, and monitoring practices.
Skipping the "what happens when it is wrong" design step. Teams often test a feature with clean, expected questions, watch it work, and ship it, then discover in week two that real customers ask messy, unexpected things the feature was never designed to handle. Planning for that up front avoids most of the post-launch fire drills.
 Back to Blog