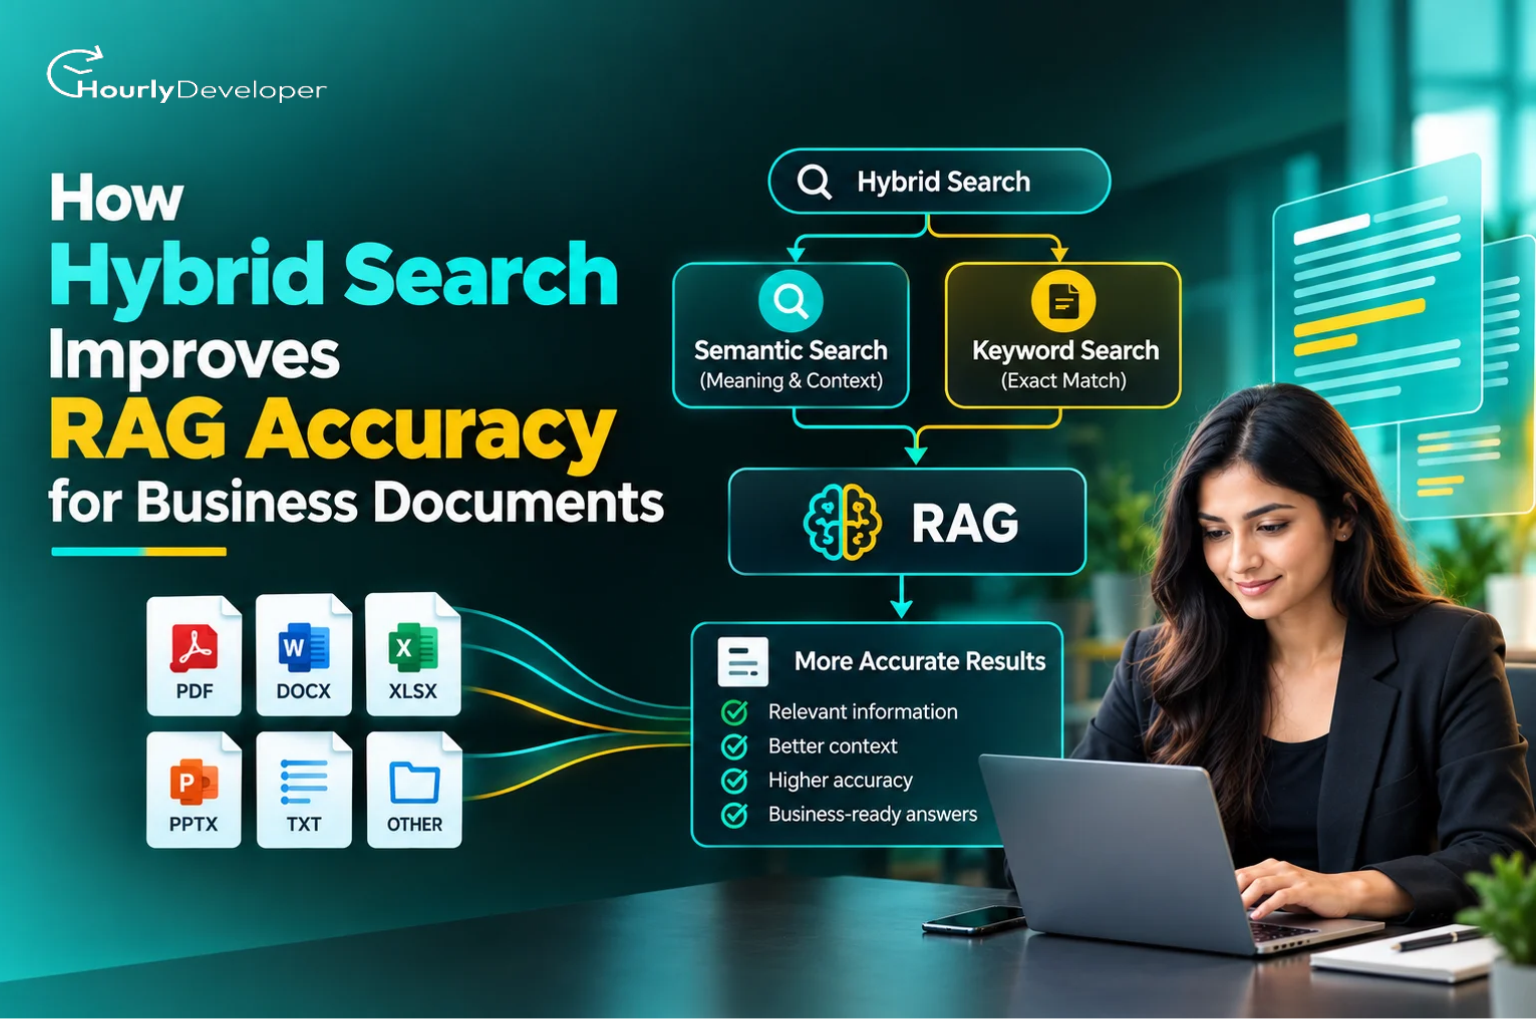
How Hybrid Search Improves RAG Accuracy for Business Documents
A procurement manager types a question into her company's new AI assistant: "What's the late delivery penalty in clause 14.3 of the Harlow Freight contract?"
The answer comes back in two seconds: a penalty of 2% per week, stated with total confidence.
The number is wrong. The assistant pulled clause 14.3 from a different carrier's contract, one written from the same template with almost the same wording about late deliveries. The Harlow contract says 5%. In this made-up but very common kind of case, nobody notices until an invoice dispute sends someone back to the original PDF three weeks later.
The AI model did its job. It read the page it was given and summarised it correctly. The mistake happened one step earlier, when the system fetched the wrong page.
That search step decides most of what business AI assistants get right or wrong. This article explains how hybrid search improves RAG accuracy when your documents are contracts, HR policies, product manuals, invoices, and all the other paperwork a company runs on. Wherever a technical term comes up, I'll explain it.
First, what RAG does
RAG stands for retrieval-augmented generation. The name is clunky, but the idea is simple. Before the AI answers your question, it searches your documents, picks out the passages that look most relevant, and reads them. Then it writes an answer based on what it just read.
Think of it as an open-book exam. The AI model is the student. Your document library is the textbook. RAG is the rule that says, "Look it up before you answer."
To make this work, the system first cuts every document into smaller pieces called chunks, such as a paragraph or a section, and stores them in a search index. When a question arrives, the system searches those chunks, grabs a small handful (usually somewhere between 5 and 20), and passes them to the AI model along with the question.
The model can only work with what it's handed. If the right chunk isn't in that handful, the model either admits it can't find the answer or builds one from the wrong chunk, which is how you get a confident 2% that should have been 5%.
This is why people doing serious RAG development end up spending most of their time on the search side. You can switch to a smarter AI model and still get wrong answers if the search keeps handing it the wrong pages.
Keyword search: great with exact words
The older of the two search methods is keyword search. Document systems have used it for decades.
The most common version is called BM25. You don't need the formula. Here's what it does in plain terms:
▪ It looks for chunks that contain the words in your question.
▪ It gives extra credit to rare words. If your question includes "Harlow" and "penalty," the word "Harlow" counts for much more, because it shows up in only a few documents while "penalty" shows up in hundreds.
▪ It adjusts for length, so a long chunk that mentions a word once doesn't beat a short chunk that is clearly about that topic.
Keyword search is at its best with anything exact. Invoice numbers, clause numbers, product codes like SKU-44871, employee IDs, medicine names, legal terms, and client names all fall in this group. If the word appears in both the document and the question, keyword search will find it.
Its weakness is that it only sees letters, not meaning. Ask "How many days of time off do I get?" and it may miss the HR policy titled "Annual Leave Entitlement," because none of your words appear in it. It also trips over typos. To a basic keyword index, "reimbursment" and "reimbursement" are two unrelated words.
Vector search: great with meaning
The newer method is vector search, often called semantic search. It tries to match meaning instead of exact words.
A special AI model, called an embedding model, reads each chunk and turns it into a long list of numbers. That list is called a vector, or an embedding. The numbers work like coordinates on a map of meaning. Chunks about similar ideas end up close to each other on that map, even when they use completely different words. "Annual leave," "vacation days," and "paid time off" all land in the same neighbourhood.
When a question comes in, it gets turned into numbers the same way. The system then looks for the chunks sitting closest to the question on the map.
This works well for everyday questions. People don't talk like policy documents. They ask, "Can I work from my parents' place in another city for a month?" and vector search can link that to a remote work policy that never uses those words.
Vector search has blind spots too, and business documents run into them all the time:
▪ Exact identifiers. To an embedding model, "clause 14.3" and "clause 13.4" mean nearly the same thing. So do invoice INV-20931 and INV-20913. Numbers carry very little meaning, so they barely change where a chunk sits on the map.
▪ Company jargon. If your team calls a project "Bluefin" or uses an internal code like "QBR-L," the embedding model has probably never seen it and has no idea what it refers to.
▪ Near-duplicate documents. Two contracts built from the same template look almost identical in meaning. That's exactly what went wrong with Harlow Freight.
▪ Negation. "Plans that cover dental" and "plans that don't cover dental" sit very close together on the map, because they're about the same subject.
So each method is strong where the other is weak. That simple fact is the whole reason hybrid search exists.
Hybrid search: run both, then merge the results
Hybrid search sends the same question to a keyword search and a vector search at the same time. Then it combines the two result lists into one.
The combining is the tricky part. Keyword search might give a chunk a score of 14.2, while vector search gives the same chunk 0.83. Those numbers aren't on the same scale, so you can't simply add them.
The most popular fix is called Reciprocal Rank Fusion, or RRF. It ignores the raw scores and only looks at position in each list. First place earns the most points, second place a little less, and so on. The usual formula gives a chunk 1 divided by (60 + its rank) from each list and adds the two together. The 60 is a standard setting that stops a single first-place finish from dominating everything.
A small example shows how this plays out. Say we search for the Harlow penalty clause and get these results:
Chunk
Keyword rank
Vector rank
RRF score
Final position
Harlow contract, clause 14.3
1
2
0.0325
1st
Brennan contract, clause 14.3
5
1
0.0318
2nd
Harlow rate appendix
2
Not in top 10
0.0161
3rd
General late delivery FAQ
Not in top 10
3
0.0159
4th
The Brennan contract was vector search's favourite, because its wording about late deliveries matched the question almost perfectly. But keyword search noticed that it never mentions Harlow, so it ranked it fifth. The Harlow contract did well in both lists, and that agreement pushed it to the top. RRF rewards results that both methods like.
Some systems use a different merging method called weighted blending. Both sets of scores are converted to a 0 to 1 scale and then mixed, for example 70% vector and 30% keyword. That mixing ratio is often called alpha. It gives you more control, but it needs tuning, and a ratio that suits HR policies may be wrong for a parts catalogue.
Many teams also add a third step called a reranker. A reranker is a separate model that reads the question and each candidate chunk side by side and scores how well that chunk answers the question. It is more careful than either search, but also slower, so it only looks at the shortlist. Microsoft's Azure AI Search, for instance, reranks up to the top 50 merged results. You can think of the two searches as a quick screening round and the reranker as the proper interview.
Getting these three layers to work together is a large part of what AI search development looks like in practice. Each layer is simple alone; tuning how they cooperate on your documents is the real work.
Why business documents need both kinds of search
Business documents are packed with exact references that keyword search handles well, yet people ask about them in casual language that vector search handles better.
Contracts are full of clause numbers, party names, and defined terms, and many share a template, which makes them hard to tell apart by meaning alone. Keyword search locks onto the right party. Vector search finds the right clause when someone asks, "What happens if they deliver late?"
HR policies are written formally, but employees ask about them informally. Vector search does most of the work here. Keyword search still matters when someone refers to a policy code like HR-POL-017 or asks about "the 2025 version."
Financial reports carry figures, quarter labels, and account codes. "Q3 FY25 EBITDA" is keyword territory. "Why did margins drop last quarter?" is meaning territory.
Real users ask both kinds of question, sometimes in one sentence. "Does the warranty on the X200 cover water damage?" needs keyword search to pin down X200 and vector search to understand that "water damage" matches a clause about "liquid ingress."
Keyword vs vector vs hybrid search: a side-by-side comparison
What you're comparing
Keyword search (BM25)
Vector search
Hybrid search
How it matches
Exact words and word forms
Similar meaning
Both, merged into one list
Best at
Codes, names, numbers, legal terms
Casual questions, synonyms, rewording
Mixed questions that need both
Struggles with
Synonyms, typos, vague questions
Exact IDs, jargon, near-duplicate files
Balancing the two sides
Typos
Poor unless fuzzy matching is added
Fairly tolerant
Tolerant, thanks to the vector side
Brand-new internal jargon
Finds it as soon as it's indexed
Often misses it
Finds it through the keyword side
Setup effort
Low
Medium
Medium to high
Storage needed
Small
Large
Largest (two indexes)
Speed per query
Very fast
Fast
Fast, a little slower than either alone
Can you see why a result appeared?
Yes, the matching words are visible
Hard, it's a distance between numbers
Partly
What the research and market figures say
BY THE NUMBERS
▸ In a September 2024 study, Anthropic measured how often the right chunk failed to appear in the top 20 results. A standard embedding setup missed 5.7% of the time. Adding context to each chunk brought that down to 3.7%. Adding keyword search on top (a hybrid setup) dropped it to 2.9%, a 49% reduction. Adding a reranker brought it to 1.9%, a 67% reduction overall.
▸ Microsoft's Azure AI Search team tested its retrieval modes on customer data and academic benchmarks and reported that hybrid retrieval with its semantic reranker gave the most relevant results in most cases.
▸ Menlo Ventures' 2024 State of Generative AI in the Enterprise report, based on a survey of 600 companies, found RAG in use in 51% of enterprise AI setups, up from 31% in 2023.
▸ Grand View Research put the global RAG market at USD 1.2 billion in 2024 and expects about 49.1% yearly growth through 2030, reaching roughly USD 11 billion.
▸ Mordor Intelligence gives different figures: USD 1.92 billion in 2025, rising to USD 10.2 billion by 2030, at about 39.7% yearly growth.
The two market forecasts don't line up, and that's normal. Research firms define "the RAG market" differently and start from different years. They agree on the direction, so treat any single number as a rough estimate.
A fair warning about benchmarks
Anthropic's tests used codebases, fiction, and scientific papers, not contracts or HR files. Microsoft's tests included customer data, but not yours. The pattern repeats across studies, with hybrid beating either method alone, yet the size of the gain on your documents is something you have to measure yourself.
Put simply, the research answers how hybrid search improves RAG accuracy in a practical way: the right chunk lands in the shortlist more often, and the AI has fewer chances to answer from the wrong page.
The hard parts that never show up in demos
Demos run on clean documents and friendly questions. Real companies have neither.
Data gaps: when the text isn't really there
A scanned contract is a picture of text, not text. Without a text layer, both indexes see a blank page. Optical character recognition (OCR) software can read the picture and turn it into text, but it makes mistakes. A zero becomes the letter O, a lowercase L becomes a one, and "INV-20931" turns into "INV-2O931." Keyword search then misses it completely, and vector search doesn't care about the difference either way. Check a sample of OCR output before indexing.
Tables cause a different kind of gap. When a pricing table is flattened into plain text, the link between each number and its row disappears. "Standard 5% Express 8% Same-day 12%" is hard for any search to make sense of. A better approach is to turn each row into its own sentence, such as "Late penalty for express delivery: 8% per week," before indexing.
Then there's lost context. A chunk might say "The Supplier shall pay 5% of the order value per week of delay" without ever mentioning Harlow, because the company name only appears on page one. A search for "Harlow" can't match a chunk that doesn't contain the word. The fix is to add a short line of context to each chunk before indexing, such as the document title, the parties involved, and the section heading. That is the idea behind Anthropic's "contextual retrieval," where an AI model writes a sentence of context for every chunk.
Sometimes the answer simply isn't in your documents. Hybrid search will still return its top ten of something, because search always returns results. It never says "nothing matched." You need a minimum relevance score, ideally from the reranker, and an instruction telling the AI to say "I couldn't find this in the documents" when nothing clears that bar.
Companies that hire AI developers for a project like this are often surprised that the first few weeks go into cleaning documents rather than tuning search. That's normal, and it's usually time well spent.
Pro tip
Before changing a single search setting, open 20 random chunks from your index and read them as if you were the AI. If you can't tell which client, product, or policy a chunk belongs to, the AI can't tell either.
Conflicting signals: when the two searches disagree
Sometimes the keyword list and the vector list barely overlap. That disagreement is useful information. It usually means the question contains both an exact term and a fuzzy idea. RRF keeps the strongest candidates from both lists near the top, so the reranker or the AI gets to see both options. That's usually better than letting one method decide alone.
When the lists share almost nothing, the question may be vague, and some systems ask the user a follow-up instead of guessing.
A bigger problem is conflicting documents. Suppose the 2022 travel policy says economy class for all flights, while the 2025 version allows business class for flights over six hours. Both match the question well. Search has no way of knowing which one is current.
The fix is metadata, which just means labels stored alongside each chunk. Useful labels include the effective date, the status (active or replaced), the department, and the region. Replaced documents can be filtered out by default. When two active documents genuinely disagree, such as a travel policy for the India office and a different one for the UK office, the better approach is to pass both to the AI and tell it to explain the difference and cite each, rather than silently choosing one.
Different teams can also pull the balance in different directions. Legal questions lean on exact terms. HR questions lean on meaning. A single global setting for the keyword and vector mix is always a compromise, so some systems adjust it by department or by document type.
Real-time decisions: speed versus care
Every extra step adds waiting time, and a customer in a support chat is less patient than an employee. So the system has to decide, question by question, how much work to do:
▪ The keyword and vector searches run in parallel, so hybrid search adds little beyond the slower of the two, plus the merge, which is quick.
▪ The reranker is usually the slowest step, because it reads each candidate in full. Reranking fewer candidates makes it faster.
▪ For exact lookups, like a single invoice number where keyword search already has a clear winner, the reranker can often be skipped. Microsoft's own guidance notes that reranking adds little when the first stage returns fewer than five results.
▪ A simple check on the question can shift the balance. A question containing a code pattern, such as letters followed by a dash and digits, can lean on keyword search. A long, chatty question can lean on vector search.
Freshness is another real-time issue. Say a new contract is uploaded at 10 a.m. The keyword index can usually add it within seconds. The vector index has to wait for the embedding model to process it, which takes longer, especially with a large batch of files or a busy API. During that gap, hybrid search can still find the new contract through the keyword side. A vector-only system would act as though it doesn't exist.
Deletions matter even more. If a withdrawn policy or a former employee's file is removed from one index but its vectors stay in the other, the assistant may keep quoting it. Every deletion has to reach both indexes. Small details like this separate careful AI search development from a weekend prototype.
Exceptions and edge cases
A handful of everyday situations break simple setups:
▪ One-word questions. Type "leave" and both searches return a vague pile. It works better to spot very short questions and ask what the person means.
▪ Pasted emails as questions. A 300-word email with a signature and a legal disclaimer at the bottom makes keyword search match on words like "confidential" and "regards." Stripping signatures, or having the AI rewrite the email as a short question first, fixes most of this.
▪ Acronyms with two meanings. "PO" means purchase order to the finance team and post office to the mailroom. "CR" might be a change request or a credit. A company glossary that expands acronyms in both documents and questions helps both searches.
▪ Other languages. An employee in a regional office asks a question in Hindi about a policy written in English. Keyword search finds nothing, since no words are shared. A multilingual embedding model can still connect the two, so the vector side carries the search.
▪ Numbers and ranges. "Contracts worth more than $50,000" means nothing to either search, because neither understands "more than." Store amounts as proper number fields and filter on them.
▪ Negative questions. "Which suppliers are not ISO certified?" pulls up documents about ISO certification, and the AI has to separate yes from no. A structured supplier list often answers this better than free text.
How the system behaves under pressure and at scale
A setup that works on 500 documents can struggle at 5 million chunks. At that size, vector databases stop comparing the question against every chunk, because that would take too long. They use shortcuts called approximate nearest neighbour indexes. A common one is HNSW, which checks a clever subset of chunks instead of all of them. It's much faster, but now and then it misses the true best match. Hybrid search acts as a safety net here. If the vector side skips a chunk, the keyword side may still catch it.
Storage grows quickly. One million chunks with 1,536 numbers each, at 4 bytes per number, adds up to about 6 GB of raw vector data before any index overhead. A keyword index over the same text is much smaller. Compression methods can shrink vectors a lot, at the cost of a small drop in accuracy.
Permissions are where many systems quietly break. Not every employee should see every document, so results get filtered by access rights. If that filtering happens after the search, a junior employee might get only 5 usable results out of 50, because the other 45 were restricted. Microsoft's documentation describes this same shrinking effect. Filtering before the search avoids it but can be slower on some systems. Always test with your most restricted user, the person who can see the least.
Busy periods, like month-end close, bring their own pressure. Caching common answers helps. So does a timeout rule that falls back to keyword-only search if the vector service is slow. A slightly weaker answer beats a spinning wheel.
Finally, switching embedding models later means re-processing every chunk, because vectors from two models can't be mixed. The keyword index is unaffected, which is one more reason to keep it.
Careful RAG development plans for these issues from day one, because adding permissions or re-processing a large library after launch is slow and expensive.
What users notice
Likely cause
What to try
Answers quote the wrong client or contract
Chunks lack document context, or files share a template
Add title and party names to each chunk; give keyword search more weight
Codes, IDs, or clause numbers aren't found
Vector-only search, or OCR mistakes
Add the keyword side; check a sample of OCR text
Casual questions come back empty
Keyword-only search
Add the vector side; build a synonym list
An old policy gets quoted
No version labels
Tag effective dates and status; filter out replaced files
Slow answers at busy times
Reranking too many candidates
Rerank fewer; cache common questions; skip reranking for exact lookups
A confident answer when no answer exists
No relevance cutoff
Set a minimum reranker score and allow "not found"
Some staff get thin, unhelpful answers
Permission filter applied after search
Filter first, or fetch more candidates before filtering
A practical order for building it
If you're planning a hybrid setup for your own documents, this order tends to work well:
1.Collect 50 to 100 real questions from the people who will use the system, and note the correct document for each one. This becomes your test set.
2.Clean the documents. Extract the text, fix OCR problems, turn tables into readable rows, and remove headers and footers that repeat on every page.
3. Split documents into chunks along their headings where possible, and add a short context line with the title, parties, and section to each chunk.
4.Build the keyword index and the vector index from the same chunks.
5.Merge the results with RRF, starting with the standard setting.
6.Measure. For each test question, check whether the correct chunk appears in the top 10. Write that percentage down.
7.Add a reranker and measure again. Keep it only if the improvement is worth the extra wait.
8.Add metadata filters for dates, status, department, and permissions.
9.Watch real use. Every question that gets a thumbs-down or a "not found" goes into the test set.
Step 6 is the one most teams skip, and it's where good RAG development separates itself from guesswork. Without a test set, you're adjusting settings by feel. With one, you can see in plain numbers how hybrid search improves RAG accuracy on your own files instead of trusting someone else's benchmark.
When hybrid search isn't worth the effort
Hybrid search means two indexes to keep in sync, more storage, and more settings to tune. Sometimes that's more than the job requires.
If you only have 30 or 40 short policy documents, today's AI models may be able to read all of them in one prompt.
If your content has almost no exact identifiers, such as a library of meeting notes or blog posts where people only ask loose, open questions, vector search alone may perform well. Test it before adding a second index.
And if users only ever type in order numbers, you don't need AI search at all. A normal database lookup will be faster, cheaper, and always correct.
For most collections of real business documents, though, the mix of codes, names, and casual questions makes hybrid search the safer default.
Building it yourself or bringing in help
Getting a basic version running is the easy part now. Search tools such as Elasticsearch, OpenSearch, Weaviate, Qdrant, and Azure AI Search offer hybrid queries out of the box, and PostgreSQL can do it with the pgvector extension alongside its built-in full-text search. A developer comfortable with Python can have a working prototype within a few days.
The hard part is everything after the prototype: messy PDFs, permissions, test sets, version conflicts, and behaviour under load. That calls for a mix of skills, including search tuning, document processing, testing, and backend engineering. Many small teams don't have all of them in-house.
If that's your situation, it can make sense to hire AI developers who have built retrieval systems before, which is a different skill from building chatbots. When you talk to candidates or agencies, a few questions reveal a lot quickly. Have they built a test set and measured how often the right document was found? How did they handle document permissions? What did they do about scanned files? Can they explain why a particular result ranked where it did?
If someone talks only about which AI model to use and never mentions search, data cleanup, or testing, treat that as a warning sign. Experienced AI search development teams usually start with your documents and your questions, not with the model.
Key takeaways
Most wrong answers from business AI assistants start with the search step, not the AI model.
Keyword search is strong with exact codes, names, and numbers. Vector search is strong with meaning and casual wording.
Hybrid search runs both and merges the results, usually with RRF, so each method covers the other's blind spots.
A reranker can improve the final order but adds waiting time, so use it where it clearly helps.
Clean documents, context on each chunk, version labels, and permission checks matter as much as the search method.
Build a test set from real questions and measure before and after every change.
Final thoughts
Go back to the Harlow Freight contract. The fix there wasn't a cleverer AI model. It was making sure the search step could see the word "Harlow" and the idea of a "late delivery penalty" at the same time. That's the short answer to how hybrid search improves RAG accuracy: it lets exact matching and meaning-based matching cover for each other, so the AI starts from the right page far more often.
If you're starting out, begin with real questions from real users, clean up the documents, and measure everything. If your team lacks retrieval experience, it's worth taking the time tohire AI developerswho can show you measured results from past projects.
Ayush, the visionary Director leading our team towards new horizons. With a passion for innovation and a keen eye for opportunities, Ayush drives our company's growth with unwavering determination. His strategic thinking and empathetic leadership inspire us all to achieve greatness together.
Frequently Asked Questions
No. Semantic search is another name for vector search, which matches by meaning. Hybrid search combines semantic search with keyword search and merges both result lists, so it catches exact terms that semantic search alone tends to miss.
Not always. Elasticsearch, OpenSearch, and PostgreSQL with the pgvector extension can all hold both kinds of index in one place. A separate vector database mostly makes sense at very large scale.
Only slightly, in most cases. The keyword and vector searches run at the same time, and merging the lists is quick. The bigger delay usually comes from a reranker, and you can control that by reranking fewer results or skipping it for simple lookups.
It reduces one of the main causes, which is the AI being handed the wrong information. It can't remove the problem entirely. You still need a relevance cutoff, clear instructions to say "not found," and answers that cite their source documents so people can check them.
Look at the questions it gets wrong. If the failures involve codes, names, clause numbers, or internal terms, you're probably missing the keyword side. If it fails on casually worded questions, you're probably missing the vector side. When you're unsure, hire AI developers or ask your current team to run a small test set through both setups and compare how often each one finds the right document.
Find exceptional developers at Hourlydeveloper. Get the expertise, solutions, and teamwork you need for success. Hire developers easily and boost your projects today!
 Back to Blog